` blocks (the 1,451 tokens include reasoning), but the final code is correct.
**Codestral: 60 → 94.** Also switched to argparse, passing all 7 functional tests. But it missed error handling entirely — no `try/except` blocks, no input validation. Its `complete` command also silently deletes the record instead of marking it done. Functional but sloppy.
### The New Models
**Gemma 4** wrote the most polished code of any model in either round. 171 lines with a dedicated `Colors` class for ANSI escape codes, emoji status indicators (✅, ⏳, 🎉, 🗑️), full `try/except/finally` blocks on every database operation, and a clean argparse architecture. It writes like a senior developer who actually cares about user experience.
**Kimi K2** wrote clean, minimal code — 87 lines with `with` context managers for database connections (the most Pythonic approach of any model), proper `sys.exit(1)` on errors, and a formatted table output. It scored 94 instead of 100 because one functional test failed: the delete command reported "Task 2 not found" due to the model storing its database at `~/.todo.db` (a global path) instead of a relative path. Stale data from an earlier test run interfered. The code logic is correct — it's a test isolation issue, not a bug.
## Style Comparison How Each Model Writes
The code style differences are telling:
**Gemma 4** (171 lines): Enterprise polish. ANSI color class, emoji, docstrings on every function, defensive error handling everywhere. The code you'd put in a demo.
**Qwen 3.5** (144 lines): Also polished — ANSI codes, structured table output, exit-on-error patterns. More defensive than Gemma but less decorative.
**Devstral** (98 lines): Minimal and correct. Flat functions, no class, CURRENT_TIMESTAMP in SQL. The code you'd actually ship.
**Kimi K2** (87 lines): Even more minimal. Context managers everywhere, zero waste. Reads like it was written by someone who's read a lot of production Python.
**DeepSeek R1** (84 lines): Compact with colorama dependency — the only model that imported an external library. Risky in an isolated test environment.
**Codestral** (80 lines): The shortest, and it shows. No error handling, buggy complete command. Brevity at the cost of correctness.
## The Speed Tiers
Round 2 reveals three distinct performance tiers for local inference:
### Tier 1 VRAM-Native ~10-35 Seconds
Models that fit entirely in the RTX 5090's 32 GB VRAM. Response times competitive with cloud APIs.
| Model | Size | Total Time | Tok/s |
|---|---|---|---|
| Devstral 24B | 14 GB | 9.97s | 70.5 |
| Codestral 22B | 12 GB | 10.01s | 82.5 |
| Gemma 4 27B | 9.6 GB | 11.77s | 167.1 |
| DeepSeek R1 14B | 9 GB | 12.44s | 116.7 |
| Qwen 3.5 MoE 35B | 23 GB | 35.23s | 142.5 |
### Tier 2 NVMe-Offloaded ~19 Minutes
Models too large for VRAM, paging from NVMe via mmap. Functional but glacial.
| Model | Size | Total Time | Tok/s |
|---|---|---|---|
| Kimi K2 1T | 579 GB | 1,141s | 0.6 |
The gap between tiers is **~100x**. Gemma 4 at 167 tok/s vs Kimi K2 at 0.6 tok/s. Both wrote correct code. One took 12 seconds, the other took 19 minutes.
This isn't a criticism of Kimi K2 — it's a 1 trillion parameter model running on hardware that costs less than a month of cloud API credits. The fact that it works at all is the story. The fact that it wrote correct, clean, well-structured code is the punchline.
## Round 1 vs Round 2 Combined Leaderboard
| Model | Round | Size | Tok/s | Score |
|---|---|---|---|---|
| **Gemma 4 27B** | R2 | 9.6 GB | 167.1 | 100 |
| Sonnet 4.6 | R1 | Cloud | 104.2 | 100 |
| Devstral 24B | R2 | 14 GB | 70.5 | 100 |
| Opus 4.6 | R1 | Cloud | 74.3 | 100 |
| Qwen 3.5 MoE 35B | R2 | 23 GB | 142.5 | 100 |
| DeepSeek R1 14B | R2 | 9 GB | 116.7 | 100 |
| Codestral 22B | R2 | 12 GB | 82.5 | 94 |
| Kimi K2 1T | R2 | 579 GB | 0.6 | 94 |
Gemma 4 is now the fastest model with a perfect score — local or cloud. A 9.6 GB model running on consumer hardware, outperforming Anthropic's Sonnet 4.6 on raw throughput while matching it on code quality.
The local-vs-cloud gap hasn't just closed. On this task, local won.
## What We Learned
**Configuration matters more than model selection.** Three models went from failing to perfect with two setting changes. If your local models are underperforming, check your token limits and prompt clarity before blaming the model.
**The prompt is still the variable.** Round 1's "ambiguous CLI" issue was a prompt problem, not a model problem. Six words ("NOT interactive input") fixed two models.
**VRAM is the cliff.** The performance difference between "fits in VRAM" and "doesn't fit in VRAM" is 100x. There's no gradual degradation — you're either generating at 70-167 tok/s or you're at 0.6. If your model fits, you're competitive with cloud. If it doesn't, you're watching paint dry.
**Big models can still write good code slowly.** Kimi K2 at 0.6 tok/s is impractical for interactive coding. But for batch processing, overnight code generation, or "I need an answer and I don't care when" use cases, a 1T model on consumer NVMe is a real option that didn't exist a year ago.
**Gemma 4 is the new default.** Fastest throughput, perfect score, smallest download, most polished output. If you're running a homelab with a single GPU, it's the model to install first.
## What's Next Gemma vs Opus a Real Fight
Round 1 tested a toy todo app. Round 2 fixed the settings and added models. Both rounds answered a useful question: can local models write correct code for a well-defined task?
The answer is yes. Five out of six scored perfect. That question is settled.
The next question is harder: **can a local model replace my daily driver on a real task?**
My daily driver is Opus 4.6. It's what I use for everything on [vibescoder.dev](https://vibescoder.dev) — features, refactors, debugging, the works. It's also a cloud model with per-token costs, rate limits, and a dependency on someone else's infrastructure.
Gemma 4 just beat every model in the benchmark on speed and matched the best on quality. It runs locally on my 5090 at 167 tok/s with zero API costs. The obvious question: can it actually do the job?
Round 3 will be a head-to-head. Gemma 4 vs Opus 4.6, same task, but not a toy. We're going to pick a real feature from the vibescoder.dev backlog — something that touches multiple files, requires architectural decisions, and has enough ambiguity to separate a good model from a great one. The kind of task I'd normally hand to Opus without thinking.
If Gemma holds up, local-first AI coding isn't just viable for benchmarks. It's viable for production.
## By the Numbers
- **6** local models benchmarked (up from 4 local + 2 cloud in Round 1)
- **5** perfect scores (up from 3)
- **579 GB** downloaded over 3 hours 27 minutes for Kimi K2
- **375 seconds** to load 579 GB into memory-mapped NVMe
- **68.9 seconds** for Kimi K2's first token
- **1,140 seconds** (19 minutes) for Kimi K2's total generation
- **9.6 GB** for Gemma 4 — smallest model, highest score + speed
- **167.1 tok/s** from Gemma 4 — fastest perfect-scoring model across both rounds
- **0.6 tok/s** from Kimi K2 — slowest, but correct
- **16,384** token limit that saved Qwen from another truncation
- **2 GPU layers** out of ~60+ that fit in VRAM for Kimi K2
- **3** Round 1 bugs fixed by configuration changes, not model changes
- **1** llama-cli conversation mode bug worked around with llama-server
- **0** API costs for everything
===
## Downtime Is a Feature: Custom Domains, Cloudflare, and MCP While Models Download
- URL: https://vibescoder.dev/posts/downtime-is-a-feature-custom-domains-cloudflare-and-mcp
- Date: 2026-04-25
- Tags: #coder #cloudflare #homelab #mcp #agents
- Reading time: 11 min read
While waiting for massive open source models to download, I tackled the homelab backlog: custom domain for my Coder instance via Cloudflare Tunnel, security hardening (with a gotcha that could kill your AI search visibility), and wiring up MCP servers to give agents superpowers.
---
You know how it goes in AI development — sometimes you're stuck watching progress bars crawl forward. I've been preparing for the next installment of the Local Model Showdown series, and that means downloading some hefty models. Kimi K2.6 decided to take its sweet time. We're talking *hours*.
But here's the thing: downtime is really just opportunity in disguise. Instead of watching percentages tick up, I knocked out three items from the backlog that had been bugging me for a week. All done conversationally through [Coder Agents](https://coder.com/agents), naturally.
The hit list:
1. Put my self-hosted Coder instance behind a real domain
2. Harden the Cloudflare setup (and discover a gotcha that every content creator needs to know)
3. Wire up MCP servers to give my agents superpowers
## The Goal Coder.vibescoder.dev
My Coder instance was running on my homelab Ubuntu workstation, accessible through a `try.coder.app` tunnel URL — functional but ugly, hard to remember, and not exactly on-brand. I bought `vibescoder.dev` for the blog. Time to use `coder.vibescoder.dev` for the dev environment.
Sounds simple. It wasn't.
## Attempt 1 CNAME Records the Naive Approach
First move was straightforward — add CNAME records in Vercel's DNS management (since I bought the domain through Vercel) pointing the `coder` subdomain to the existing tunnel URL.
**Gotcha #1**: Vercel's DNS form defaults to record type "A" (which expects an IPv4 address). Spent a minute confused by the "value should match format ipv4" error before realizing I needed to switch the Type dropdown to "CNAME." Small thing, but it'll trip you up if you're not looking at the form defaults.
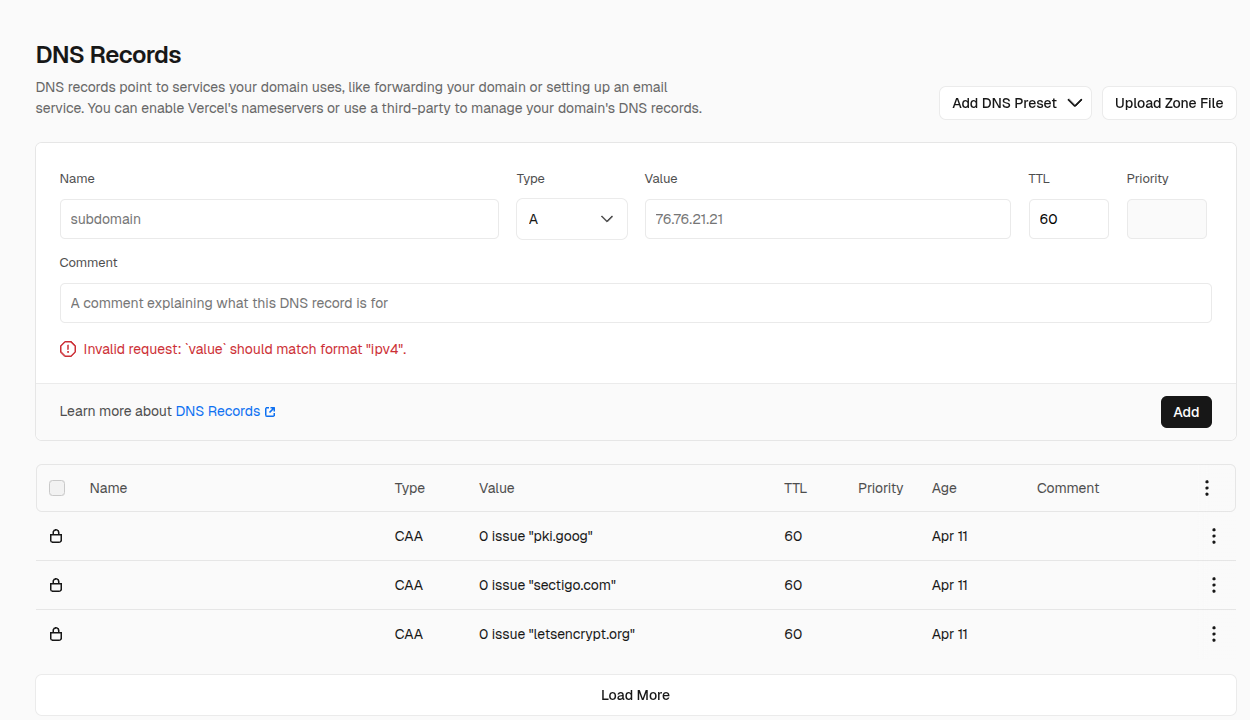
*Vercel's DNS form defaults to an A record — switch the type to CNAME or you'll get this unhelpful error.*
Then I went to update the Access URL in Coder's dashboard. Deployment → General → Access URL. It's right there on the screen... and it's read-only. The UI shows you the value but can't change it. The badges underneath tell the story: `CLI --access-url`, `ENV CODER_ACCESS_URL`, `YAML accessURL`. Server config only.
Since Coder runs via systemd on my homelab, the config lives at `/etc/coder.d/coder.env`. But before I could update it, I needed to solve the bigger problem: getting traffic from the internet to my machine.
## Attempt 2 Port Forwarding the Frustrating Detour
For a CNAME-based approach to work, my homelab needs to be reachable from the internet on ports 80 and 443. That means port forwarding on the router — a TP-Link Archer BE800.
**The router app doesn't expose port forwarding.** The Tether iPhone app has a "More" menu with various settings, but NAT Forwarding isn't there. Had to use the web interface at `192.168.0.1` instead. Found it under Advanced → NAT Forwarding → Port Forwarding.
Set up the rules: ports 80 and 443, TCP, forwarded to my machine's internal IP (`192.0.2.243`). Then tested with a simple Python HTTP server:
```bash
sudo python3 -c "from http.server import HTTPServer, SimpleHTTPRequestHandler; HTTPServer(('0.0.0.0', 443), SimpleHTTPRequestHandler).handle_request()"
```
Local curl worked. External requests to my public IP? "Connection refused." Not a timeout — *refused*. Tried non-standard ports too. Same result.
**The diagnosis**: "Connection refused" from outside while "works locally" means traffic is reaching the public IP but getting actively rejected before it hits the machine. The ISP is likely blocking inbound connections or there's a NAT layer beyond the router. A timeout would mean packets are being dropped. Refused means something is saying "no."
I spent more time on this than I'd like to admit. Time for Plan B.
## The Solution Cloudflare Tunnel
Cloudflare Tunnel flips the model entirely. Instead of opening inbound ports, it creates an *outbound* connection from your machine to Cloudflare's edge. No port forwarding. No router config. No public IP exposure. And it's free.
### Step 1 Move Nameservers
Since I needed Cloudflare to manage DNS for `vibescoder.dev`, I:
1. Created a free Cloudflare account
2. Added `vibescoder.dev` as a site
3. Let it auto-import my existing DNS records (Vercel A records, CAA records, everything)
4. Selected the Free plan
5. Updated nameservers at Vercel (the registrar) to point to Cloudflare's nameservers
The blog continues to work — Cloudflare imported all existing records, so `vibescoder.dev` still routes to Vercel's servers.
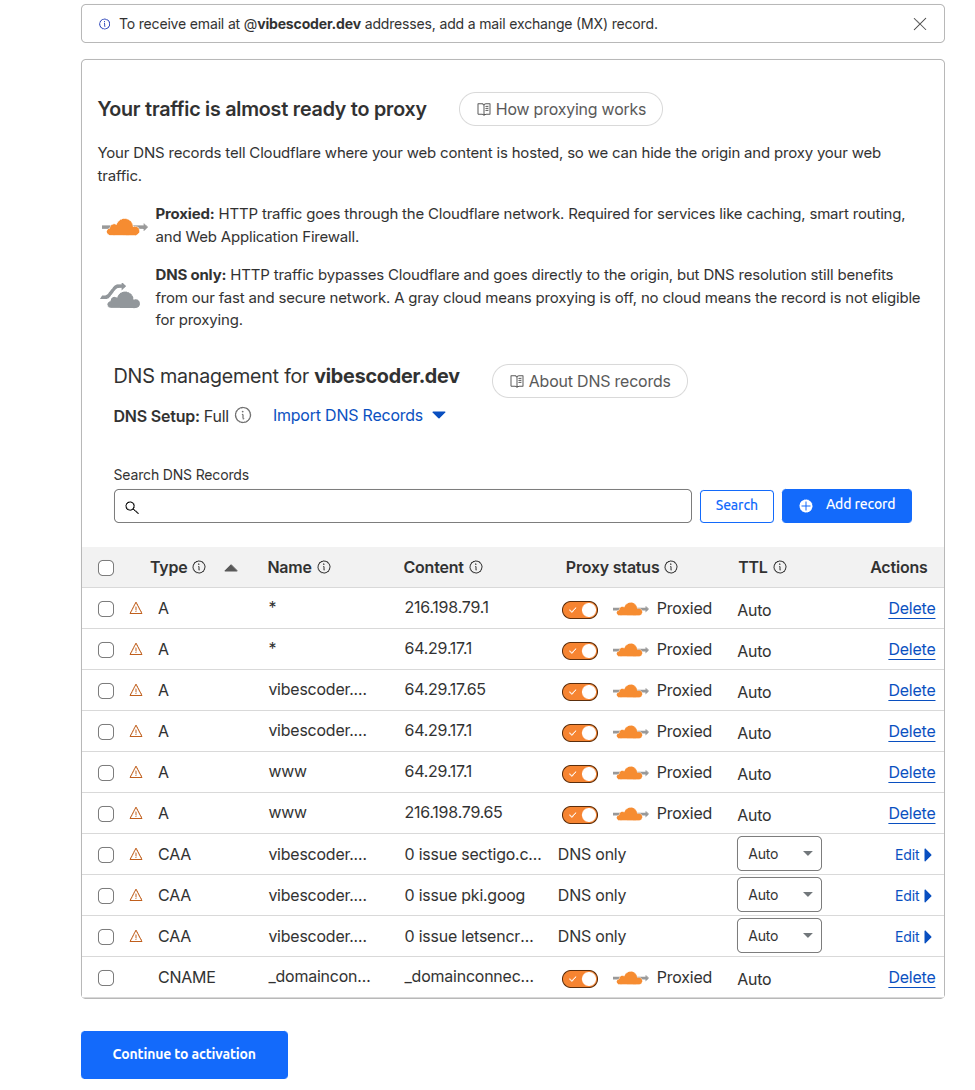
*Cloudflare auto-imports your existing DNS records — the blog keeps working while you set up the tunnel.*
### Step 2 Create the Tunnel
On the homelab machine:
```bash
curl -L --output cloudflared.deb https://github.com/cloudflare/cloudflared/releases/latest/download/cloudflared-linux-amd64.deb
sudo dpkg -i cloudflared.deb
cloudflared tunnel login
cloudflared tunnel create coder-tunnel
```
*After `cloudflared tunnel login`, the browser confirms the certificate is installed and you're authorized.*
Config file at `~/.cloudflared/config.yml`:
```yaml
tunnel: a1b2c3d4-e5f6-7890-abcd-ef1234567890
credentials-file: /home/youruser/.cloudflared/a1b2c3d4-e5f6-7890-abcd-ef1234567890.json
ingress:
- hostname: coder.vibescoder.dev
service: http://localhost:3000
- hostname: "*.coder.vibescoder.dev"
service: http://localhost:3000
- service: http_status:404
```
The wildcard entry handles Coder's app proxying — port forwarding, web terminals, and workspace apps all use subdomains like `8080--main--ws--user--coder.vibescoder.dev`.
### Step 3 Wire up DNS and Coder
```bash
cloudflared tunnel route dns coder-tunnel coder.vibescoder.dev
cloudflared tunnel route dns coder-tunnel "*.coder.vibescoder.dev"
```
Updated `/etc/coder.d/coder.env`:
```
CODER_ACCESS_URL=https://coder.vibescoder.dev
CODER_WILDCARD_ACCESS_URL=*.coder.vibescoder.dev
```
Restarted Coder, ran the tunnel — four connections registered to Cloudflare's SJC edge locations. Opened `https://coder.vibescoder.dev` in a browser. Coder login screen. Done.
### Step 4 Make It Permanent
**Gotcha #2**: `sudo cloudflared service install` couldn't find the config. It looks in `/etc/cloudflared/`, not `~/.cloudflared/`. Had to copy both files:
```bash
sudo mkdir -p /etc/cloudflared
sudo cp ~/.cloudflared/config.yml /etc/cloudflared/config.yml
sudo cp ~/.cloudflared/*.json /etc/cloudflared/
```
Updated the `credentials-file` path in the copied config to point to `/etc/cloudflared/`, then:
```bash
sudo cloudflared service install
sudo systemctl enable cloudflared
sudo systemctl start cloudflared
```
Two systemd services now: `coder` and `cloudflared`. Both start on boot. The architecture:
```
Browser → https://coder.vibescoder.dev
→ Cloudflare Edge (TLS termination, DNS)
→ Cloudflare Tunnel (outbound from homelab)
→ localhost:3000 (Coder server)
```
Zero inbound ports. Zero public IP exposure. Free TLS from Cloudflare. Survives reboots.
## Hardening Cloudflare and the AI Crawler Gotcha
With Cloudflare in front of everything, I reviewed the security settings. Here's what's worth enabling on the free tier:
| Setting | What it does |
|---------|-------------|
| **SSL/TLS → Full (strict)** | Ensures encryption all the way to the origin, not just browser-to-Cloudflare |
| **Bot Fight Mode** | Challenges malicious bots — scrapers, credential stuffers, spam |
| **DDoS Protection** | Already active by default |
| **Always Online** | Serves cached pages if your origin goes down |
The **WAF Managed Ruleset** (SQL injection, XSS protection) requires a Pro plan. Skipped for now.
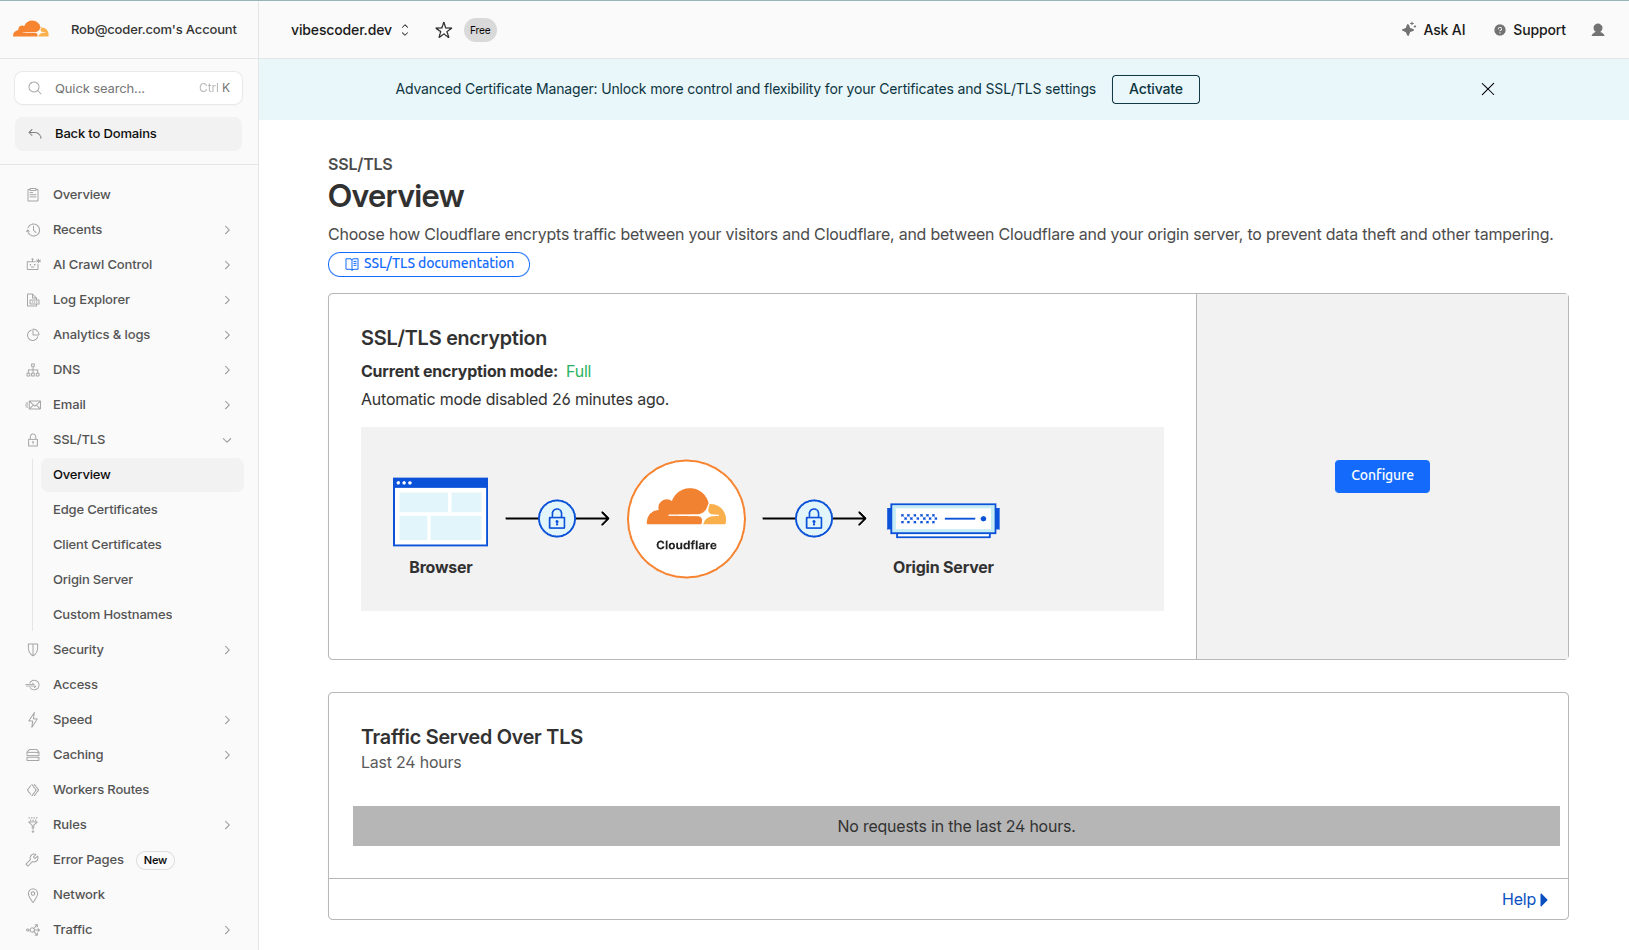
*Set SSL/TLS to Full (strict) to encrypt traffic all the way from Cloudflare to your origin server.*
### The Part Every Content Creator Needs to Read
Cloudflare's free tier includes two AI-related settings that are **on by default**:
1. **Block AI bots** — Blocks bots Cloudflare categorizes as AI training crawlers (GPTBot, CCBot, Google-Extended, etc.)
2. **AI Labyrinth** (Beta) — Injects fake AI-generated content into your pages to poison bots that ignore crawling standards
Both sound great if you want to protect your content from being scraped. But think about what these actually do: they block the crawlers that feed ChatGPT search, Perplexity, Google AI Overviews, and every other AI-powered discovery tool.
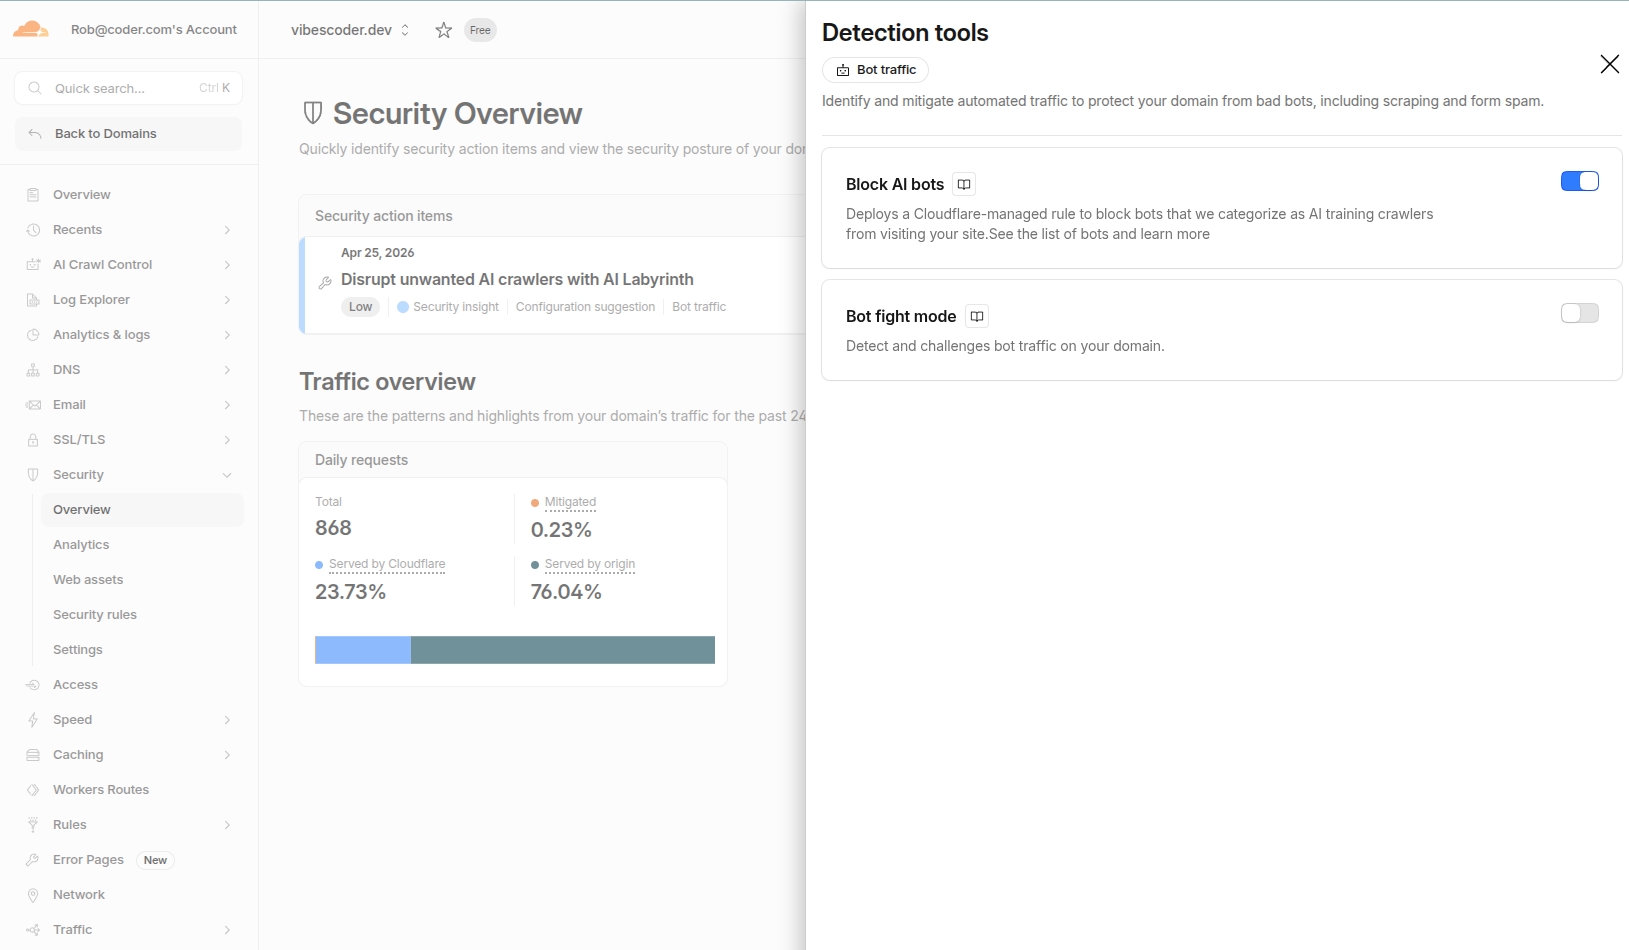
*This innocent-looking toggle blocks the AI crawlers that power ChatGPT search, Perplexity, and Google AI Overviews.*
**If your site exists for thought leadership, you *want* AI services to find, index, and cite your content.** That's the entire point. Blocking AI crawlers is blocking your distribution channel.
The distinction:
- **Block AI bots / AI Labyrinth** = blocks crawlers that feed AI search and training. Kills discoverability.
- **Bot Fight Mode** = blocks malicious bots. Doesn't affect legitimate AI crawlers.
I turned both **Block AI bots** and **AI Labyrinth off**, while keeping Bot Fight Mode on. If you're running a personal brand, a company blog, or anything where you care about AI-powered search visibility — check these settings immediately after onboarding to Cloudflare. The defaults optimize for content protection, not content distribution.
## MCP Giving Agents Superpowers
With the infrastructure sorted, I moved to the fun part: MCP (Model Context Protocol) integration. MCP lets AI agents access external tools — think of it as a plugin system for LLMs.
### The AI Gateway
Two lines in `coder.env` unlock the big stuff:
```
CODER_EXPERIMENTS=oauth2,mcp-server-http
CODER_EXTERNAL_AUTH_0_MCP_URL=https://api.githubcopilot.com/mcp/
```
The first enables Coder's experimental MCP support. The second wires GitHub's MCP server into Coder's AI Gateway. Since I already had GitHub OAuth configured, this means the gateway automatically injects GitHub tools (prefixed with `bmcp_`) into every agent's LLM requests. Every agent in every workspace gets GitHub repo access, PR management, issue tracking — zero per-workspace config.
### Choosing MCP Servers
Researched the ecosystem and selected five servers based on this specific stack:
| MCP Server | Why |
|-----------|-----|
| **GitHub** (official, 29K stars) | Blog content is a private GitHub repo. Handled via AI Gateway. |
| **Context7** (Upstash, 53K stars) | Feeds current library docs to LLMs instead of hallucinated APIs. Critical for Next.js 16. |
| **Vercel** (official) | Check deployments, read build logs, manage env vars. |
| **Cloudflare** (official, 3.6K stars) | DNS analytics, tunnel debugging, observability. |
| **Playwright** (Microsoft, 31K stars) | Visual testing of blog deployments. |
What I deliberately skipped: **Ollama-specific MCP servers**. This is a common misconception worth calling out. You don't need an "Ollama MCP server." Ollama is the LLM backend — agents call it for inference. MCP servers provide *tools* (GitHub access, deployment management, browser automation). The agent uses Ollama to *think* about what to do, and MCP tools to *do* it. They're separate concerns.
### Wiring It into the Template
MCP servers in Coder aren't configured in the admin panel — they're discovered via a `.mcp.json` file in the workspace root. **Gotcha #3**: I spent time looking for an MCP settings page in the Coder dashboard before discovering this.
To make it persistent across all workspaces, I edited the Docker template's `main.tf`:
```bash
coder templates pull docker .
nano main.tf # add .mcp.json to startup_script
coder templates push docker
```
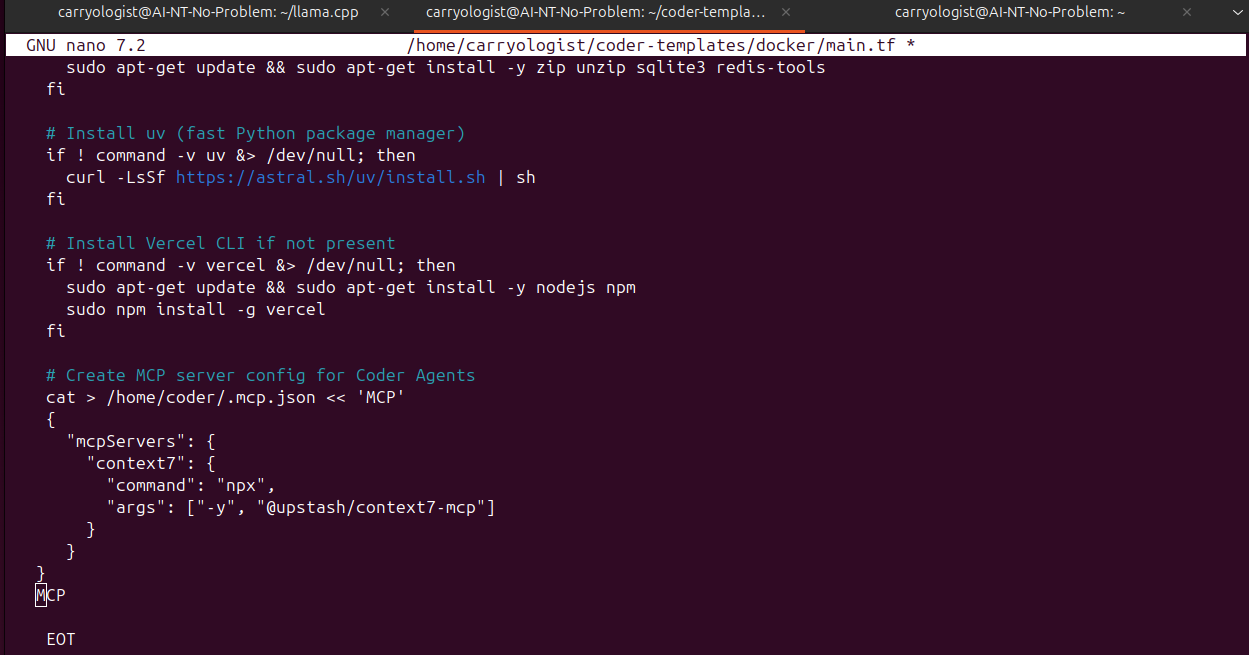
*Editing the Docker template's main.tf to inject .mcp.json into every workspace at startup.*
The startup script now writes this `.mcp.json` to every workspace:
```json
{
"mcpServers": {
"context7": {
"command": "npx",
"args": ["-y", "@upstash/context7-mcp"]
},
"vercel": {
"command": "npx",
"args": ["mcp-remote", "https://mcp.vercel.com"]
},
"cloudflare": {
"command": "npx",
"args": ["mcp-remote", "https://agents.cloudflare.com/mcp"]
},
"playwright": {
"command": "npx",
"args": ["-y", "@playwright/mcp@latest"]
}
}
}
```
Context7 and Playwright run locally as stdio processes. Vercel and Cloudflare connect to remote HTTP endpoints and handle OAuth on first use.
## The Full Stack
```
┌─────────────────────────────────────────────────────┐
│ HOMELAB (Ubuntu + RTX 5090) │
│ │
│ Ollama (local LLMs) ◄── Coder AI Gateway │
│ │ │
│ Coder Server ────────────┤ Injected tools: │
│ (systemd, port 3000) │ • bmcp_github_* │
│ │ │
│ Cloudflared ─────────────┤ │
│ (systemd, tunnel) │ │
│ │ │
│ Workspace (.mcp.json): │ │
│ • context7 (stdio) │ │
│ • playwright (stdio) │ │
│ • vercel (remote HTTP) │ │
│ • cloudflare (remote HTTP) │
└───────────────┬─────────────────────────────────────┘
│ Cloudflare Tunnel
▼
┌─────────────────────────────────────────────────────┐
│ EXTERNAL SERVICES │
│ │
│ Cloudflare Edge (DNS, TLS, DDoS, Bot Fight Mode) │
│ GitHub (content repo, MCP via AI Gateway) │
│ Vercel (blog hosting, MCP remote server) │
│ Anthropic Claude (blog post generation) │
│ Upstash Redis (analytics) │
└─────────────────────────────────────────────────────┘
```
## By the Numbers
- 2 port forwarding rules attempted (failed — ISP blocking)
- 1 Cloudflare Tunnel created (0 inbound ports required)
- 4 environment variables changed in `coder.env`
- 2 systemd services running (coder + cloudflared)
- 5 Cloudflare security settings reviewed
- 2 AI-blocking features disabled for thought leadership discoverability
- 5 MCP servers configured (GitHub via AI Gateway + 4 in .mcp.json)
- 1 workspace template updated
- 3 gotchas discovered (Cloudflare AI defaults, `.mcp.json` discovery, `cloudflared` config paths)
- ~2 hours of productive "downtime" while models downloaded
===
## Friday Fixes: This Week's Minor Site Improvements
- URL: https://vibescoder.dev/posts/friday-fixes-a-walkthrough-of-this-weeks-minor-site-improvements
- Date: 2026-04-25
- Tags: #agents #meta #building-in-public
- Reading time: 10 min read
Code block overflow, social metadata, dynamic OG images, Slack notifications for blog comments, a /todo slash command, and more. Everything shipped in a single conversational session with Coder Agents.
---
After a week of publishing meaty infrastructure posts, the site itself needed attention. Small bugs that I'd been ignoring, missing social previews, no way to know when someone left a comment. The kind of stuff that piles up when you're focused on content instead of the platform.
So I sat down with [Coder Agents](https://coder.com/agents) and knocked out nine improvements in a single conversation. No local IDE, no task switching. Just describing problems and letting the agent fix them, commit, and deploy. Here's every fix, what caused it, and what I learned.
## 1 Code Block Overflow on Mobile
**The problem**: On mobile, long lines in code blocks were clipping instead of scrolling. The `[OK] GPU: NVIDIA GeForce RTX 5090 (32607 MiB...` line in the home lab post was getting cut off with no scrollbar.
**Root cause**: The `` component had `overflow-x-auto`, but the `` element inside it was inheriting styles from the shared `InlineCode` component: background, border, padding, smaller font size. That created a clipping box inside the scrollable container.
**The fix**: One line in `MDXComponents.tsx`. Added Tailwind `[&>code]` child selectors on the `Pre` component to reset background, border, padding, border-radius, font size, and text color when `code` appears inside `pre`.
The kind of bug where the symptom (clipped text) and the cause (inline code styling leaking into block code) live in completely different mental models. The agent traced it immediately.
## 2 Mobile Table Layout
**The problem**: The four-column model table in the [Coder Agents post](/posts/putting-the-gpu-to-work-running-local-llms) was unusable on mobile. The "Why" column was wrapping to a single word per line.
**The fix**: Dropped the column entirely. The reasoning for each model already existed in the "Why These Models" section above the table. Three columns fit cleanly on any screen width.
Sometimes the best fix is removing content, not adding responsive tricks.
## 3 Social Metadata Overhaul
**The problem**: Sharing a blog post URL in Slack showed the wrong preview. The site-wide defaults ("Vibes Coder" with the old green-bar OG image) were appearing instead of the post's actual title and description.
**Two root causes**:
1. The post page's `generateMetadata` only returned `title` and `description` without explicit `openGraph` or `twitter` tags. Social crawlers fell back to the layout-level defaults.
2. Those defaults still had old branding from before the rebrand.
**The fixes**:
- Post `generateMetadata` now emits full `openGraph` (title, description, URL, article type, published date) and `twitter` card metadata.
- All site-wide metadata updated from "Vibes Coder" to "vibescoder" with the current description.
- Regenerated `opengraph-image.png` with the purple waveform, `vibes`/`coder` wordmark, and dark background matching the current design system. Used sharp (already in the Next.js dependency tree) with an SVG-to-PNG pipeline.
- RSS feed title updated to match.
- Rendered a proper 512x512 favicon PNG from the waveform icon for platforms that need a raster favicon.
## 4 Dynamic OG Images per Post
The static OG image fix got sharing working, but every post shared the same generic card. For a site that publishes multiple posts a week, each link in Slack or Twitter should show its own title card.
**The solution**: A Next.js `opengraph-image.tsx` route inside `posts/[slug]/` that generates a branded 1200x630 social card per post using `ImageResponse`. Each card includes:
- The post title (large, bold)
- Formatted date and reading time
- The purple waveform mark
- `vibes` / `coder` wordmark at the bottom
If the post contains images, the first one is composited as a subtle background at 15% opacity behind the title card. Posts without images get a clean branded card. The site-level `opengraph-image.png` remains the fallback for non-post pages like the homepage and about page.
Static params are generated at build time, so every published post gets its own card with zero runtime cost.
## 5 Giscus Comment Notifications in Slack
**The problem**: No way to know when someone leaves a blog comment. Giscus backs onto GitHub Discussions, but the repo owner isn't auto-subscribed to discussions that Giscus creates on behalf of commenters.
**The solution**: A GitHub Actions workflow (`.github/workflows/giscus-notify.yml`) that triggers on `discussion_comment` created events, filtered to the Announcements category. Sends a Slack Block Kit message via incoming webhook with:
- Commenter avatar and username
- Comment body (truncated to 500 chars)
- "Reply on GitHub" button that deep-links to the comment
- "View on Blog" button constructed from the discussion title
The comment body is read from `$GITHUB_EVENT_PATH` via `jq` rather than `${{ }}` expression interpolation to avoid shell injection.
**Gotcha**: Giscus creates discussion titles as `posts/my-slug` (no leading slash), not `/posts/my-slug`. Both the notification workflow's URL construction and the comment count matching had to account for this.
## 6 Comment Count Badges
**The problem**: No visual indication of engagement on the homepage. A post with ten comments looked identical to one with zero.
**The solution**: A new `discussions.ts` module fetches comment counts from the GitHub Discussions REST API. It's a public endpoint (no auth needed, 60 req/hr rate limit) cached with `next: { revalidate: 300 }` for five-minute staleness. Returns a `Record` mapping slugs to counts.
The homepage fetches posts and comment counts in parallel via `Promise.all`, merges them, and passes the data to `PostCard`. Cards now show a chat bubble icon and count in the metadata line (next to date and reading time) when a post has one or more comments.
Small touch, but it gives readers a reason to click through to posts that have an active conversation.
## 7 Slack `/Todo` Slash Command
**The problem**: Updating the project TODO list meant opening GitHub, navigating to the content repo, editing `content/TODO.md`, and committing. Way too much friction for capturing a quick idea.
**The solution**: A Vercel API route at `/api/slack/todo` that receives Slack slash commands, verifies the HMAC-SHA256 signature, and appends items to TODO.md via the GitHub Contents API.
```
/todovc Fix the RSS feed → adds to "Up Next"
/todovc backlog: Explore MCP → adds to "Ideas / Backlog"
```
The route parses the command text for an optional `backlog:` prefix, fetches the current TODO.md (including its SHA for optimistic concurrency), inserts `- [ ] item` at the end of the target section, and commits with a descriptive message.
**Security**: Slack signs every request with a shared signing secret. The route verifies the signature using `crypto.createHmac` with timing-safe comparison. No valid signature, no write. Reuses the existing `GITHUB_TOKEN` that the build pipeline already has, so no new PAT was needed.
**Bugs hit during implementation**:
1. TypeScript's `/s` (dotAll) regex flag isn't available below es2018 target. Vercel's tsconfig targets below that. Fixed with `[\s\S]` equivalent.
2. The auth middleware was blocking all `/api/*` routes with an admin session check. Slack doesn't send cookies, so it got a 401 before the route handler ever ran. Fixed by adding `/api/slack/*` to the middleware allowlist. Safe because the route handles its own auth via HMAC.
## 8 CollapsibleCode Label Fix and Collapsed Preview
**The problem**: The `` component wasn't showing its label. In MDX, every usage passes a `label` prop, but the component was expecting `title`.
**Root cause**: A prop name mismatch. The component was built with `title`, but when it was used in actual blog content, the natural prop name was `label`. Nobody noticed because the component still expanded and collapsed fine; you just couldn't see what it contained until you clicked.
**The fixes**:
- Accept both `label` (preferred) and `title` (deprecated, for backward compat).
- Added a faded preview of the first few lines when collapsed. Uses `max-h-24` with a gradient overlay that fades to the surface color. Readers can see a glimpse of the code before deciding to expand, instead of staring at a blank clickable bar.
## 9 Slack App Wiring
This isn't a code change, but it's worth documenting because it took more steps than you'd think. The Slack app connects two features: incoming webhooks for comment notifications (feature 5) and the `/todovc` slash command (feature 7).
1. Created a Slack app from scratch (not from manifest, since all we needed was a webhook and a slash command)
2. Incoming Webhooks: toggled on, added to `#vibes-coder` channel
3. Slash Commands: created `/todovc`, pointed at `https://vibescoder.dev/api/slack/todo`
4. Added `SLACK_WEBHOOK_URL` as a GitHub repo secret (for the Actions notification workflow)
5. Added `SLACK_SIGNING_SECRET` as a Vercel env var (for slash command verification)
6. Redeployed on Vercel (env vars don't hot-reload on running deployments)
Two env vars, one Slack app, two completely different integrations. Took longer to navigate the Slack admin UI than to write the code.
## What I Learned
**Small bugs compound.** None of these were urgent individually. But collectively they meant: posts looked bad when shared, mobile readers hit clipped code, comments happened in silence, and capturing ideas required six clicks. Knocking them all out in one session changed how the site feels to use.
**Agents are great at the boring middle.** Writing the Slack HMAC verification, wiring up GitHub API calls for TODO.md, tracing a CSS inheritance chain through three component layers. These are tasks that require attention to detail but not creative judgment. Perfect agent territory.
**Prop mismatches are the new typo.** The CollapsibleCode bug was invisible for days because the component worked, it just didn't show its label. When AI generates components and AI writes the MDX that uses them, a prop name drift between `title` and `label` is the kind of thing neither side catches unless you're reading the rendered output carefully.
**Dynamic OG images are worth the effort.** Every post shared on Slack or Twitter now has its own branded card with the title, date, and reading time. It took one file and zero runtime cost (statically generated at build time). If you're running a Next.js blog and sharing links regularly, this is a high-leverage addition.
---
## Files Changed
- `src/components/MDXComponents.tsx` — code block overflow fix
- `src/components/CollapsibleCode.tsx` — label prop fix + collapsed preview
- `src/app/layout.tsx` — metadata branding update
- `src/app/posts/[slug]/page.tsx` — per-post social metadata
- `src/app/posts/[slug]/opengraph-image.tsx` — new, dynamic OG images
- `src/app/opengraph-image.png` — regenerated site-level OG image
- `src/lib/discussions.ts` — new, comment count fetcher
- `src/lib/types.ts` — added `commentCount` to Post
- `src/app/page.tsx` — comment counts merged into post list
- `src/components/PostCard.tsx` — comment count badge
- `src/app/api/slack/todo/route.ts` — new, slash command endpoint
- `src/middleware.ts` — Slack routes added to auth allowlist
- `.github/workflows/giscus-notify.yml` — new, comment notification workflow
- `public/images/branding/favicon-512x512.png` — new, raster favicon
## What's Next
The home lab has two new models queued up for testing. **Kimi K2.6** is Moonshot AI's latest, and early benchmarks put it in competitive territory with the frontier cloud models. The collective wisdom is that I should do API-only for now (too large for consumer VRAM), but worth profiling on the homelab rig against the cloud options we benchmarked in the [model showdown](/posts/llm-model-showdown-benchmarking-local-vs-cloud). Any guesses on if we can crack 2 tokens/sec? **Gemma 4** from Google is the other one on the list. We're still researching whether it fits in 32 GB of VRAM, but Google's been making noise about 6x VRAM efficiency improvements, so it might land squarely in home lab territory.
Both were requested by the dev team after reading the showdown results. Round 2 is coming.
## By the Numbers
- **9 improvements** shipped in one conversation
- **14 files** changed across both repos
- **3 new features** (dynamic OG images, comment notifications, /todo command)
- **4 bug fixes** (code overflow, table layout, social metadata, CollapsibleCode label)
- **2 Slack integrations** from 1 Slack app
- **1 new env var** needed (`SLACK_SIGNING_SECRET`; everything else reused existing tokens)
- **0 new dependencies** added
- **5-minute cache** on comment counts
- **0 runtime cost** for OG image generation (static at build time)
===
## Model Showdown: Benchmarking Local vs Cloud LLMs on a Real Coding Task
- URL: https://vibescoder.dev/posts/llm-model-showdown-benchmarking-local-vs-cloud
- Date: 2026-04-22
- Tags: #ai #llm #benchmark #homelab
- Reading time: 18 min read
We gave six LLM models the exact same coding prompt and measured everything: speed, tokens, and whether the code actually works. Three models scored perfect. Two built the wrong kind of app. One ran out of tokens mid-line.
---
Last post we stood up Ollama on the RTX 5090, pulled a stack of models, and wired them into our coding workflow. The whole time there was an obvious question hanging over it: are local models actually good enough?
Not good enough in the abstract benchmarks-on-a-leaderboard sense. Good enough for the thing we’re journaling: vibe coding. Specifically, can a model running on consumer hardware in my homelab produce code that's as correct, as fast, and as complete as what comes back from Anthropic's cloud?
We built a benchmark to find out.
## The Setup
Six models, one prompt, no second chances.
**Cloud (Anthropic API):**
- Sonnet 4.6 (`claude-sonnet-4-20250514`)
- Opus 4.6 (`claude-opus-4-20250514`)
**Local (Ollama on RTX 5090, 32 GB VRAM):**
- Codestral 22B (`codestral:22b`)
- DeepSeek R1 14B (`deepseek-r1:14b`)
- Devstral (`devstral:latest`)
- Qwen 3.5B MoE (`qwen3.5:35b-a3b`)
The prompt was intentionally straightforward: build a Python CLI todo app with SQLite persistence, CRUD commands (add, list, complete, delete), timestamps, pretty output, error handling, and a `__main__` block. The kind of task that shows up in real work. A simple "write a small, complete program."
Every model got the exact same prompt with the instruction: "Respond with ONLY the Python code, no explanation."
We measured:
- **Time to first token (TTFT)**: how long before output starts streaming
- **Total generation time**: wall clock from request to last token
- **Output tokens**: how much the model wrote
- **Tokens per second**: raw generation throughput
- **Validation**: does it parse, does it have all the features, does it actually run through a functional test suite of 7 operations (add two todos, list, complete one, list again, delete one, list again)
## The Results Performance
| Model | Type | TTFT | Total Time | Output Tokens | Tok/s |
|---|---|---|---|---|---|
| Sonnet 4.6 | Cloud | 0.87s | 14.89s | 1,461 | 104.2 |
| Opus 4.6 | Cloud | 1.23s | 19.06s | 1,324 | 74.3 |
| Codestral 22B | Local | 15.81s | 22.11s | 620 | 98.5 |
| DeepSeek R1 | Local | 11.74s | 20.64s | 1,707 | 191.7 |
| Devstral | Local | 2.24s | 10.26s | 723 | 90.2 |
| Qwen 3.5B | Local | 28.20s | 30.91s | 4,096 | 1,510.2 |
A few things jump out immediately. Devstral finished faster than every other model, cloud or local. Qwen's tokens-per-second number is absurd. And DeepSeek R1 produced the most tokens despite writing roughly the same amount of code as (more on why in a minute).
## The Results Quality
Performance doesn't matter if the code is wrong. Here's how each model scored:
| Model | Syntax Valid | Features (X/10) | Functional (X/7) | Score |
|---|---|---|---|---|
| Sonnet 4.6 | Yes | 10/10 | 7/7 | 100 |
| Opus 4.6 | Yes | 10/10 | 7/7 | 100 |
| Devstral | Yes | 10/10 | 7/7 | 100 |
| Codestral 22B | Yes | 10/10 | 0/7 | 60 |
| DeepSeek R1 | Yes | 10/10 | 0/7 | 60 |
| Qwen 3.5B | No | 7/10 | 0/7 | 28 |
Three perfect scores. Two models that wrote valid code that didn't pass functional tests. One that didn't even produce valid Python.
Let's talk about what happened.
## What Went Wrong and Right
### The Interactive Menu Problem
Codestral 22B and DeepSeek R1 both scored 10/10 on features. Their code had SQLite, all four CRUD operations, timestamps, completion tracking, error handling, a main block, and pretty output. On paper, they nailed it.
The problem: both interpreted "Commands: add, list, complete, delete" as an interactive menu application. They built `while True` loops with `input()` prompts instead of CLI argument parsers.
Codestral's approach:
```python
while True:
action = input("Enter a command (add, list, complete, delete): ")
```
DeepSeek R1 went even further, building an entire menu system:
```python
print("Todo App Menu:")
print(" ---")
print("add - Add a new todo ")
print("list - List all todos ")
cmd = input("Enter command: ").strip().lower()
```
Both are perfectly valid interpretations of "commands." Both produced clean, working code. But our automated test suite calls the script with command-line arguments (`python todo.py add "Buy groceries"`), not interactive input. The scripts immediately hit `EOFError: EOF when reading a line` because there's no stdin to read from.
This is arguably a prompt clarity issue, not a model quality issue. If the prompt had said "using argparse" or "using sys.argv," both models would have nailed it. But the three models that scored 100 all inferred CLI arguments without being told, which is the more common pattern for "command-line app" in the training data.
### The Token Limit Trap
Qwen 3.5B is fascinating and frustrating in equal measure.
That 1,510 tokens-per-second number is real. The model uses a Mixture of Experts (MoE) architecture: 35 billion total parameters, but only ~3 billion active per token. The RTX 5090 tears through it. In pure generation speed, nothing else comes close.
But it hit the 4,096 output token limit mid-f-string:
```python
print(f"{'ID':<5} {'Status':<8} {'Title':<40} {'Created At'}")
print('-' * 70)
for row in rows:
id_, title, created_at, completed = row
status = "[X]" if completed else "[ ]"
print(f"{
```
That's it. The code cuts off right there. No closing quote, no remaining functions, no main block. The syntax is invalid. The features for `complete`, `delete`, and `__main__` are missing because the model never got to write them.
The speed is meaningless if the output is incomplete. The lesson: always set generous `max_tokens` for code generation tasks. A 4,096 limit that's fine for chat responses will absolutely truncate a complete program. We should have set 8,192 or higher. That's on us.
### DeepSeek R1's Thinking Tax
DeepSeek R1 produced 1,707 output tokens, the most of any model, but its actual code was only 156 lines. Where did the extra tokens go?
Into `` blocks. DeepSeek R1 is a reasoning model. Before writing code, it spends tokens working through the problem:
> "Let me think about how to structure this... I need SQLite for persistence... I'll use a class-based approach with a menu system..."
This is genuinely useful for hard debugging problems or complex architectural decisions. But for straightforward code generation where the answer is obvious, it's wasted compute. You're paying (in time and tokens) for the model to reason through something it could just write directly.
### Devstral's Quiet Dominance
The standout result of the entire benchmark. Devstral is a 24B parameter model from Mistral, purpose-built for coding tasks. On paper it's smaller than some of the competition. In practice:
- **Fastest total time**: 10.26 seconds, beating even the cloud models
- **Best local TTFT**: 2.24 seconds, nearly as fast as cloud cold-start
- **Perfect score**: 100/100 on quality
- **Clean architecture**: argparse-based CLI, exactly what the test expected
It didn't overthink it. It didn't build a menu system. It didn't run out of tokens. It just wrote a clean, correct, well-structured todo app and moved on.
## Code Comparison the Three Perfect Scores
All three 100-score models (Sonnet, Opus, Devstral) used argument-based CLI patterns, but their implementations differ in interesting ways.
**Sonnet 4.6** went with `argparse` and a class-based design. 149 lines. Full docstrings, type hints, and emoji-rich output with status indicators:
```python
class TodoApp:
def __init__(self, db_path: str = "todos.db"):
self.db_path = db_path
self.init_database()
def add_todo(self, title: str):
# ...
print(f"✅ Added todo #{todo_id}: {title.strip()}")
```
**Opus 4.6** also used a class with `sys.argv` parsing instead of argparse. 157 lines. It used `sqlite3.Row` for named column access and a manual usage printer. More defensive with explicit connection closing in a `finally` block:
```python
class TodoApp:
def __init__(self, db_path: str = "todos.db"):
self.conn = sqlite3.connect(db_path)
self.conn.row_factory = sqlite3.Row
self.create_table()
```
**Devstral** took the most minimal approach. 99 lines. Flat functions instead of a class, `argparse` with subparsers, `CURRENT_TIMESTAMP` in SQL instead of Python-side datetime generation. No emoji, no decorations, just clean output:
```python
def list_todos():
# ...
for row in rows:
status = "[x]" if row[3] else "[ ]"
print(f"{row[0]:<3} {status} {row[1]} (created at: {row[2]})")
```
The style differences are telling. Sonnet writes like a senior developer who cares about DX. Opus writes like someone who's been burned by unclosed connections before. Devstral writes like someone who bills by the hour and values conciseness. All three approaches are correct. Devstral's is the one I'd actually want in a codebase.
```python
import sqlite3
import argparse
import datetime
from typing import List, Tuple
class TodoApp:
def __init__(self, db_path: str = "todos.db"):
self.db_path = db_path
self.init_database()
def init_database(self):
"""Initialize the SQLite database and create the todos table if it doesn't exist."""
conn = sqlite3.connect(self.db_path)
cursor = conn.cursor()
cursor.execute("""
CREATE TABLE IF NOT EXISTS todos (
id INTEGER PRIMARY KEY AUTOINCREMENT,
title TEXT NOT NULL,
created_at TEXT NOT NULL,
completed INTEGER NOT NULL DEFAULT 0
)
""")
conn.commit()
conn.close()
def add_todo(self, title: str):
"""Add a new todo item."""
if not title.strip():
print("❌ Error: Todo title cannot be empty")
return
conn = sqlite3.connect(self.db_path)
cursor = conn.cursor()
created_at = datetime.datetime.now().strftime("%Y-%m-%d %H:%M:%S")
cursor.execute(
"INSERT INTO todos (title, created_at, completed) VALUES (?, ?, 0)",
(title.strip(), created_at)
)
conn.commit()
todo_id = cursor.lastrowid
conn.close()
print(f"✅ Added todo #{todo_id}: {title.strip()}")
def list_todos(self):
"""List all todo items."""
conn = sqlite3.connect(self.db_path)
cursor = conn.cursor()
cursor.execute("SELECT id, title, created_at, completed FROM todos ORDER BY id")
todos = cursor.fetchall()
conn.close()
if not todos:
print("📝 No todos found. Add some with: python todo.py add \"Your task\"")
return
print("\n📋 Your Todos:")
print("-" * 60)
for todo_id, title, created_at, completed in todos:
status = "✓" if completed else "○"
status_text = "DONE" if completed else "TODO"
print(f"{status} #{todo_id:<3} [{status_text}] {title}")
print(f" 📅 Created: {created_at}")
print("-" * 60)
print(f"Total: {len(todos)} todos")
def complete_todo(self, todo_id: int):
"""Mark a todo as completed."""
conn = sqlite3.connect(self.db_path)
cursor = conn.cursor()
cursor.execute("SELECT id, title, completed FROM todos WHERE id = ?", (todo_id,))
todo = cursor.fetchone()
if not todo:
print(f"❌ Error: Todo #{todo_id} not found")
conn.close()
return
if todo[2]:
print(f"ℹ️ Todo #{todo_id} is already completed")
conn.close()
return
cursor.execute("UPDATE todos SET completed = 1 WHERE id = ?", (todo_id,))
conn.commit()
conn.close()
print(f"✅ Completed todo #{todo_id}: {todo[1]}")
def delete_todo(self, todo_id: int):
"""Delete a todo item."""
conn = sqlite3.connect(self.db_path)
cursor = conn.cursor()
cursor.execute("SELECT id, title FROM todos WHERE id = ?", (todo_id,))
todo = cursor.fetchone()
if not todo:
print(f"❌ Error: Todo #{todo_id} not found")
conn.close()
return
cursor.execute("DELETE FROM todos WHERE id = ?", (todo_id,))
conn.commit()
conn.close()
print(f"🗑️ Deleted todo #{todo_id}: {todo[1]}")
def main():
app = TodoApp()
parser = argparse.ArgumentParser(description="A simple command-line todo application")
subparsers = parser.add_subparsers(dest="command", help="Available commands")
add_parser = subparsers.add_parser("add", help="Add a new todo")
add_parser.add_argument("title", help="Todo title")
list_parser = subparsers.add_parser("list", help="List all todos")
complete_parser = subparsers.add_parser("complete", help="Mark a todo as completed")
complete_parser.add_argument("id", type=int, help="Todo ID to complete")
delete_parser = subparsers.add_parser("delete", help="Delete a todo")
delete_parser.add_argument("id", type=int, help="Todo ID to delete")
args = parser.parse_args()
try:
if args.command == "add":
app.add_todo(args.title)
elif args.command == "list":
app.list_todos()
elif args.command == "complete":
app.complete_todo(args.id)
elif args.command == "delete":
app.delete_todo(args.id)
else:
parser.print_help()
except Exception as e:
print(f"❌ Error: {str(e)}")
if __name__ == "__main__":
main()
```
```python
import sqlite3
import sys
from datetime import datetime
from typing import List, Tuple
class TodoApp:
def __init__(self, db_path: str = "todos.db"):
self.conn = sqlite3.connect(db_path)
self.conn.row_factory = sqlite3.Row
self.create_table()
def create_table(self):
self.conn.execute("""
CREATE TABLE IF NOT EXISTS todos (
id INTEGER PRIMARY KEY AUTOINCREMENT,
title TEXT NOT NULL,
created_at TIMESTAMP NOT NULL,
completed BOOLEAN NOT NULL DEFAULT 0
)
""")
self.conn.commit()
def add(self, title: str) -> None:
if not title.strip():
print("Error: Todo title cannot be empty")
return
try:
self.conn.execute(
"INSERT INTO todos (title, created_at) VALUES (?, ?)",
(title, datetime.now())
)
self.conn.commit()
print(f"✓ Added todo: '{title}'")
except Exception as e:
print(f"Error: Failed to add todo - {e}")
def list(self) -> None:
try:
cursor = self.conn.execute(
"SELECT * FROM todos ORDER BY created_at DESC"
)
todos = cursor.fetchall()
if not todos:
print("No todos found. Add one with 'add '")
return
print("\n" + "="*60)
print("TODO LIST")
print("="*60)
for todo in todos:
status = "✓" if todo["completed"] else "○"
created = datetime.fromisoformat(todo["created_at"]).strftime("%Y-%m-%d %H:%M")
print(f"{status} [{todo['id']}] {todo['title']}")
print(f" Created: {created}")
print("-"*60)
except Exception as e:
print(f"Error: Failed to list todos - {e}")
def complete(self, todo_id: str) -> None:
try:
todo_id = int(todo_id)
except ValueError:
print("Error: Invalid todo ID. Must be a number.")
return
try:
cursor = self.conn.execute(
"UPDATE todos SET completed = 1 WHERE id = ?",
(todo_id,)
)
if cursor.rowcount == 0:
print(f"Error: Todo with ID {todo_id} not found")
else:
self.conn.commit()
print(f"✓ Completed todo {todo_id}")
except Exception as e:
print(f"Error: Failed to complete todo - {e}")
def delete(self, todo_id: str) -> None:
try:
todo_id = int(todo_id)
except ValueError:
print("Error: Invalid todo ID. Must be a number.")
return
try:
cursor = self.conn.execute(
"DELETE FROM todos WHERE id = ?",
(todo_id,)
)
if cursor.rowcount == 0:
print(f"Error: Todo with ID {todo_id} not found")
else:
self.conn.commit()
print(f"✓ Deleted todo {todo_id}")
except Exception as e:
print(f"Error: Failed to delete todo - {e}")
def close(self):
self.conn.close()
def print_usage():
print("""
Usage:
python todo.py add <title> - Add a new todo
python todo.py list - List all todos
python todo.py complete <id> - Mark a todo as completed
python todo.py delete <id> - Delete a todo
""")
if __name__ == "__main__":
app = TodoApp()
if len(sys.argv) < 2:
print_usage()
sys.exit(1)
command = sys.argv[1].lower()
try:
if command == "add":
if len(sys.argv) < 3:
print("Error: Please provide a todo title")
print("Usage: python todo.py add <title>")
else:
title = " ".join(sys.argv[2:])
app.add(title)
elif command == "list":
app.list()
elif command == "complete":
if len(sys.argv) < 3:
print("Error: Please provide a todo ID")
print("Usage: python todo.py complete <id>")
else:
app.complete(sys.argv[2])
elif command == "delete":
if len(sys.argv) < 3:
print("Error: Please provide a todo ID")
print("Usage: python todo.py delete <id>")
else:
app.delete(sys.argv[2])
else:
print(f"Error: Unknown command '{command}'")
print_usage()
sys.exit(1)
finally:
app.close()
```
</CollapsibleCode>
<CollapsibleCode label="Full output: Devstral (99 lines)">
```python
import sqlite3
from datetime import datetime
import argparse
import sys
DATABASE = 'todos.db'
def init_db():
conn = sqlite3.connect(DATABASE)
c = conn.cursor()
c.execute('''CREATE TABLE IF NOT EXISTS todos (
id INTEGER PRIMARY KEY AUTOINCREMENT,
title TEXT NOT NULL,
created_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP,
completed BOOLEAN NOT NULL CHECK (completed IN (0, 1))
)''')
conn.commit()
conn.close()
def add_todo(title):
conn = sqlite3.connect(DATABASE)
c = conn.cursor()
c.execute("INSERT INTO todos (title, completed) VALUES (?, ?)", (title, False))
conn.commit()
conn.close()
def list_todos():
conn = sqlite3.connect(DATABASE)
c = conn.cursor()
c.execute("SELECT id, title, created_at, completed FROM todos ORDER BY completed, created_at")
rows = c.fetchall()
conn.close()
for row in rows:
status = "[x]" if row[3] else "[ ]"
print(f"{row[0]:<3} {status} {row[1]} (created at: {row[2]})")
def complete_todo(id):
conn = sqlite3.connect(DATABASE)
c = conn.cursor()
c.execute("UPDATE todos SET completed = 1 WHERE id = ?", (id,))
rows_affected = c.rowcount
conn.commit()
conn.close()
if rows_affected == 0:
raise ValueError(f"Todo with ID {id} not found.")
def delete_todo(id):
conn = sqlite3.connect(DATABASE)
c = conn.cursor()
c.execute("DELETE FROM todos WHERE id = ?", (id,))
rows_affected = c.rowcount
conn.commit()
conn.close()
if rows_affected == 0:
raise ValueError(f"Todo with ID {id} not found.")
def main():
parser = argparse.ArgumentParser(description='CLI todo application')
subparsers = parser.add_subparsers(dest='command')
add_parser = subparsers.add_parser('add', help='Add a new todo')
add_parser.add_argument('title', type=str, help='Todo title')
list_parser = subparsers.add_parser('list', help='List all todos')
complete_parser = subparsers.add_parser('complete', help='Mark a todo as completed')
complete_parser.add_argument('id', type=int, help='TODO ID to mark as completed')
delete_parser = subparsers.add_parser('delete', help='Delete a todo')
delete_parser.add_argument('id', type=int, help='TODO ID to delete')
args = parser.parse_args()
init_db()
try:
if args.command == 'add':
add_todo(args.title)
elif args.command == 'list':
list_todos()
elif args.command == 'complete':
complete_todo(args.id)
elif args.command == 'delete':
delete_todo(args.id)
else:
parser.print_help()
except Exception as e:
print(f"Error: {e}")
sys.exit(1)
if __name__ == '__main__':
main()
```
</CollapsibleCode>
## Speed Analysis
The performance numbers tell two very different stories depending on what you care about.
**For interactive chat and streaming**, TTFT is what matters. Cloud models dominated here. Sonnet 4.6 started streaming in 0.87 seconds. Opus in 1.23 seconds. You ask a question, you immediately see output. That responsiveness is a big part of why cloud models feel fast even when their total generation time is longer.
Local models have a fundamentally different cost model. TTFT includes model loading time, and on first request after a cold start, that loading time is significant:
- **Devstral**: 2.24s TTFT (best local, model stays warm in VRAM)
- **DeepSeek R1**: 11.74s (14B params loading into VRAM)
- **Codestral 22B**: 15.81s (22B params, larger model footprint)
- **Qwen 3.5B**: 28.20s (35B total params, 23 GB model loading from disk into VRAM despite only 3B active)
Qwen's 28-second TTFT is brutal for interactive use. You type a prompt and wait half a minute before anything appears. The MoE architecture means the full model weight file is enormous even though inference is fast once loaded.
**For batch processing and code generation**, total time and throughput matter more than TTFT. And here, the picture flips. Devstral at 10.26 seconds total beat both cloud models. Once the local models are loaded and generating, their token throughput is competitive:
| Model | Tok/s | Context |
|---|---|---|
| Qwen 3.5B | 1,510.2 | MoE architecture, 3B active params |
| DeepSeek R1 | 191.7 | Includes reasoning tokens |
| Sonnet 4.6 | 104.2 | Cloud, shared infrastructure |
| Codestral 22B | 98.5 | Full 22B model on single GPU |
| Devstral | 90.2 | 24B model, balanced speed/quality |
| Opus 4.6 | 74.3 | Cloud, larger model |
Devstral found the sweet spot: fast enough TTFT to feel responsive, fast enough generation to beat the cloud on wall-clock time, and high enough quality to score perfectly. It's the model that made me stop thinking of local inference as a compromise.
## The Verdict
**For production coding tasks**: Sonnet 4.6 or Devstral. Sonnet if you're already in the Anthropic ecosystem and want sub-second TTFT. Devstral if you want the same quality with zero API costs, zero rate limits, and total data privacy. Both scored 100. Devstral was actually faster end-to-end.
**Opus 4.6** is capable but slower and more expensive for no quality gain on this task. Its strengths show on harder problems: multi-file refactors, complex debugging, architectural decisions. For straightforward code generation, you're paying a premium for capability you don't need.
**Codestral 22B and DeepSeek R1** aren't bad models. They wrote valid, working code. The "failure" was a prompt interpretation issue that a single clarifying word would have fixed. In a conversational coding session where you can follow up, both would have corrected course immediately.
**Qwen 3.5B** is a speed demon trapped by token limits. At 1,510 tok/s it's the fastest generator by an order of magnitude, but that speed is wasted if you cap output too low. With proper `max_tokens` settings and the right tasks (short functions, completions, refactors), it could be the best option for high-throughput local work. We'll retest with higher limits.
The real takeaway isn't about which model "won." It's that **the prompt matters as much as the model**. Two models scored 60 because of a single ambiguous word in the prompt. One model scored 28 because of a configuration parameter. The gap between cloud and local quality has effectively closed for focused coding tasks. The remaining differences are in speed characteristics, token economics, and how forgiving the model is when your prompt isn't perfectly specific.
Local LLMs on consumer hardware aren't a compromise anymore. They're a legitimate option. Devstral proved it.
## What's Next Round 2
This was a useful first benchmark, but it was also a simple one. A single-file todo app with a clear spec is the kind of task where every model should do well. The interesting question is what happens when you make it harder.
Round 2 will use a more complex task: multi-file, with tests, with ambiguous requirements that force the model to make architectural decisions. We'll also adjust based on what we learned here. The prompt will be more explicit (no more "CLI or web" ambiguity that tripped up two models), and we'll give every model a larger context window and higher token limits so no one gets cut off mid-line.
We're also adding two models that came as requests from the Coder dev team:
- **Kimi K2.6** (Moonshot AI). A 1T-parameter MoE model with 32B active parameters and 256K context. It's getting strong benchmark scores and has native tool-calling support. The catch: even the most aggressively quantized version needs ~240 GB of memory, which is well beyond what the homelab can handle locally. We'll need to test this one via API.
- **Gemma 4** (Google). We need to research the available sizes and quantizations to see what fits on 32 GB of VRAM. If there's a version in the 14B-27B range, it could slot in alongside Devstral and Qwen as another local contender.
Both additions will be interesting tests of whether the "local models are good enough" conclusion holds with a harder prompt, and whether the newer model generation has closed the gap further.
## By the Numbers
- 6 models benchmarked
- 1 prompt, identical across all models
- 3 perfect scores (Sonnet 4.6, Opus 4.6, Devstral)
- 2 models that built the wrong kind of app
- 1 model that ran out of tokens mid-f-string
- 10.26 seconds for Devstral to write a complete, working todo app
- 1,510 tokens per second from Qwen 3.5B (fastest local generation)
- 0.87 seconds for Sonnet 4.6's first token (fastest TTFT)
- 28.2 seconds for Qwen's first token (slowest TTFT)
- 4,096 token limit that killed an otherwise promising run
- 32 GB of VRAM making all of this possible on a single GPU
- 0 API costs for the three local models
===
## Putting the GPU to Work: Running Local LLMs on a Home Lab
- URL: https://vibescoder.dev/posts/putting-the-gpu-to-work-running-local-llms
- Date: 2026-04-22
- Tags: #ai #homelab #llm
- Reading time: 12 min read
Installing Ollama, pulling five purpose-built models, wiring local inference into Coder Agents, and running agentic coding on an RTX 5090 workstation. 44 GB of models, zero cloud API calls, fully self-hosted.
---
[Yesterday](/posts/from-idea-to-infrastructure-standing-up-a-self-hosted-ai-dev-environment) we went from a gaming PC on a shelf to a fully configured Coder server with GitHub integration, workspace templates, and AI agents. The dev environment is running. But the RTX 5090's 32 GB of VRAM has been sitting idle, and all the AI work is still going through cloud APIs.
Today, we change that. This session was about installing Ollama, choosing the right models for different coding tasks, getting local inference running on the workstation, and then wiring it all into Coder Agents so local models show up right alongside Anthropic in the model selector. Everything here was done conversationally through [Coder Agents](https://coder.com/agents), same as always.
## Why VRAM Is the Only Spec That Matters
Before pulling any models, it helps to understand the constraint you're optimizing around. For local LLMs, that constraint is VRAM. Not CPU cores, not system RAM, not disk speed. VRAM determines what models you can run, and model size determines how useful they are.
| VRAM | What You Can Run |
|---|---|
| 8-12 GB | 7B models (Qwen3:8b, DeepSeek-Coder 6.7B) |
| 16 GB | 14B-20B models (DeepSeek R1 14B, Codestral 25.12) |
| **24-32 GB** | **27B-35B models, the sweet spot for agentic coding** |
| 32 GB+ / unified | 70B quantized, Qwen3-Coder-Next |
The 32 GB on the RTX 5090 lands squarely in the sweet spot. We can run 35B-parameter models at full quality, which is where the current generation of agentic coding models lives. The 64 GB of system RAM provides headroom for KV cache spillover when context windows get long, and the 2 TB NVMe means models load fast and we can store a whole library of them.
Only one generation model loads into VRAM at a time. Ollama automatically unloads the previous model when you switch. The embedding model is small enough to coexist with any of them.
## The Setup Script
Rather than running commands one at a time, we built a single bash script that handles the entire setup in six phases: hardware verification, Ollama install, service configuration, model pulls, verification, and a connection reference card.
The script is tailored to this exact hardware profile but the structure works for any NVIDIA GPU setup. It supports `--models-only` (already have Ollama, just pull models) and `--verify-only` (check that everything is working) flags for re-runs.
<CollapsibleCode label="Full setup script (setup-local-llm.sh)">
```bash
#!/usr/bin/env bash
# Target: AMD Ryzen 9 9950X3D / RTX 5090 32GB / 64GB DDR5 / Ubuntu 24.04 LTS
set -euo pipefail
PRIMARY_MODEL="qwen3.5:35b-a3b"
CODING_MODEL="devstral-small:24b"
REASONING_MODEL="deepseek-r1:14b"
AUTOCOMPLETE_MODEL="codestral:22b"
EMBEDDING_MODEL="nomic-embed-text"
KEEP_ALIVE="30m"
OLLAMA_HOST="127.0.0.1"
OLLAMA_PORT="11434"
# Phase 1: Verify hardware & drivers
nvidia-smi --query-gpu=driver_version,name,memory.total \
--format=csv,noheader
# Phase 2: Install Ollama
curl -fsSL https://ollama.com/install.sh | sh
# Phase 3: Configure service (keep models loaded 30min)
sudo mkdir -p /etc/systemd/system/ollama.service.d
sudo tee /etc/systemd/system/ollama.service.d/override.conf > /dev/null <<EOF
[Service]
Environment="OLLAMA_KEEP_ALIVE=${KEEP_ALIVE}"
Environment="OLLAMA_HOST=${OLLAMA_HOST}:${OLLAMA_PORT}"
EOF
sudo systemctl daemon-reload && sudo systemctl restart ollama
# Phase 4: Pull models
for model in "$PRIMARY_MODEL" "$CODING_MODEL" "$REASONING_MODEL" \
"$AUTOCOMPLETE_MODEL" "$EMBEDDING_MODEL"; do
ollama pull "$model"
done
# Phase 5: Verify
ollama run "$PRIMARY_MODEL" "What is 2+2? Reply with just the number."
curl -sf "http://${OLLAMA_HOST}:${OLLAMA_PORT}/v1/models"
# Phase 6: Connection reference
echo "Ollama API: http://${OLLAMA_HOST}:${OLLAMA_PORT}"
echo "OpenAI API: http://${OLLAMA_HOST}:${OLLAMA_PORT}/v1"
echo "Primary Model: ${PRIMARY_MODEL}"
```
</CollapsibleCode>
The real script is ~330 lines with color output, error handling, idempotent checks, and flag parsing. This is the condensed version showing the actual work.
## What Happened When We Ran It
### Phase 1 Hardware Detection
All green:
```
[OK] NVIDIA driver: 590.48.01
[OK] GPU: NVIDIA GeForce RTX 5090 (32607 MiB)
[OK] Driver 590.48.01 meets minimum requirement (550+).
[OK] System RAM: 60 GB
[OK] Available disk: 1717 GB
```
System RAM reports 60 GB instead of 64 GB. Normal; the kernel and firmware reserve some. Not a problem.
### Phase 2 Ollama Install
One curl command. Ollama v0.21.0 installed cleanly, auto-detected the NVIDIA GPU, created a systemd service, and added the user to render/video groups.
### Phase 3 Service Configuration
The important piece here is `KEEP_ALIVE=30m`. Without it, Ollama unloads models from VRAM after 5 minutes of inactivity. Loading a 23 GB model back into memory takes time, and if you're switching between coding and chatting every few minutes, you're hitting cold starts constantly. Thirty minutes keeps things warm during a real work session.
### Phase 4 Model Downloads
~44 GB pulled. One failure:
| Model | Size | Status | Notes |
|---|---|---|---|
| `qwen3.5:35b-a3b` | 23 GB | OK | Primary agentic coder. MoE, only 3B params active per token. |
| `devstral-small:24b` | - | FAILED | Registry name wrong. |
| `deepseek-r1:14b` | 9.0 GB | OK | Chain-of-thought reasoning. |
| `codestral:22b` | 12 GB | OK | Fast autocomplete for IDE tab-completion. |
| `nomic-embed-text` | 274 MB | OK | Embedding model for codebase search. |
`devstral-small:24b` doesn't exist on Ollama's registry. The correct pull is `ollama pull devstral`. Registry names don't always match what blogs and guides reference. This is the kind of thing you only learn by running it.
### Phase 5 Verification
The automated inference test returned empty. Cold-start timing issue: the bash `$()` capture returned before the model finished loading 23 GB into VRAM. Manual verification worked immediately after:
```bash
$ ollama run qwen3.5:35b-a3b "What is 2+2? Reply with just the number."
4
```
The OpenAI-compatible API endpoint confirmed working at `http://127.0.0.1:11434/v1/models`.
## Why These Models
Every model in the stack was chosen for a specific job. This isn't a "download the biggest model that fits" strategy. Different tasks have different requirements, and the right model for autocomplete is not the right model for debugging a race condition.
**Primary: `qwen3.5:35b-a3b`** is the all-rounder. Best agentic coder available in April 2026 at this VRAM tier. Mixture-of-Experts architecture means only 3B parameters are active per token despite being a 35B model. That gives you big-model quality with small-model speed. 256K context window. Strong tool-calling support. Fits comfortably in 32 GB VRAM at ~22 GB.
**Coding: `devstral`** (Mistral's agentic coding model) is trained specifically for multi-file edits, terminal automation, and code repair. Benchmarks highest on Ollama for pure coding tasks. When you need raw code generation without the overhead of reasoning chains, this is the one.
**Reasoning: `deepseek-r1:14b`** is the chain-of-thought model. It thinks before answering. Slower, but catches bugs other models miss. At 14B it only needs ~12 GB VRAM, so it loads fast and leaves headroom.
**Autocomplete: `codestral:22b`** is optimized for fast inline code completion (fill-in-the-middle). Best fit for IDE tab-complete via Continue.dev. You want this model to be fast above all else.
**Embeddings: `nomic-embed-text`** is a lightweight (274 MB) embedding model for codebase search and RAG pipelines. Small enough to run alongside any generation model without VRAM pressure.
## Wiring It into Dev Tools
With Ollama running, everything that speaks the OpenAI API format can connect to it:
```
Ollama API: http://127.0.0.1:11434
OpenAI API: http://127.0.0.1:11434/v1
API Key: ollama (placeholder, not validated)
Primary Model: qwen3.5:35b-a3b
```
### Continue.dev vs Code
<CollapsibleCode label="Continue.dev config.yaml">
```yaml
name: Local Coder
version: 1.0.0
schema: v1
models:
- name: Qwen3.5 35B (Chat/Edit)
provider: ollama
model: qwen3.5:35b-a3b
roles: [chat, edit, apply]
- name: Devstral (Coding)
provider: ollama
model: devstral-small:24b
roles: [chat, edit]
- name: Codestral (Autocomplete)
provider: ollama
model: codestral:22b
roles: [autocomplete]
- name: Nomic Embed
provider: ollama
model: nomic-embed-text
roles: [embed]
context:
- provider: code
- provider: docs
- provider: diff
- provider: terminal
- provider: codebase
```
</CollapsibleCode>
### Environment Variables
For scripts and agents that use the OpenAI client format:
```bash
export OLLAMA_HOST=http://127.0.0.1:11434
export OPENAI_API_BASE=http://127.0.0.1:11434/v1
export OPENAI_API_KEY=ollama
```
## Connecting to Coder Agents
This is the real payoff. Ollama is running, the models are loaded, and the OpenAI-compatible API is live on localhost. Now we wire it into [Coder Agents](https://coder.com/agents) so local models appear as selectable options right alongside the cloud providers.
Coder Agents runs the LLM loop in the control plane, not inside workspaces. That means the Coder server process makes the API calls directly. Since Ollama and the Coder server are running on the same machine, this is just pointing one localhost process at another. No tunnels, no port forwarding, no API keys leaving the box.
### Step 1 Add the Provider
In the Coder dashboard, navigate to **Agents > Admin > Providers** and select **OpenAI Compatible**. Coder treats any endpoint that implements the OpenAI chat completions API as a first-class provider.
Set the **Base URL** to `http://127.0.0.1:11434/v1` and enter `ollama` as the API key. Ollama doesn't validate keys, but Coder requires one, so this is a placeholder.

For **Key policy**, keep the defaults: Central API key on, user API keys off. There's no reason for individual developers to bring their own key to a local Ollama instance. Everyone hits the same GPU.
### Step 2 Add Models
Switch to the **Models** tab and add each model you want available in the Agents chat. The **Model Identifier** must match exactly what Ollama expects, because that string is sent directly to the `/v1/chat/completions` endpoint.

We added two models to start:
| Model Identifier | Display Name | Context Limit |
|---|---|---|
| `qwen3:35b-a3b` | Qwen 3.5B | 32,768 |
| `devstral` | Devstral | 131,072 |
The **Cost Tracking**, **Provider Configuration**, and **Advanced** sections can all be skipped for local models. No token pricing to track (it's your own GPU), and the default generation parameters work fine.
### Step 3 Use It
That's it. The models now appear in the Agents model selector dropdown alongside the existing Anthropic models. Pick one, start a conversation, and the entire inference loop runs on the local GPU.

### What Surprised Us
They work. Not "sort of work" or "work for simple prompts." The local models handle real agentic tasks through Coder Agents: reading files, running shell commands, editing code across multiple files, and reasoning about the results. Devstral in particular was impressive for code-focused work.
The latency difference compared to cloud providers is noticeable but not a dealbreaker. First-token time is slower because the model is running on a single consumer GPU rather than a cluster, but once inference is rolling, the throughput is solid. For the kind of iterative coding tasks Coder Agents handles, the tradeoff is worth it: zero API costs, zero data leaving your network, and no rate limits.
The practical recommendation: keep your cloud provider (Anthropic, OpenAI, whatever you're already using) as the default for complex, multi-step tasks. Use the local models for focused coding work, experimentation, and anything where you want to iterate fast without watching a billing dashboard.
## Ollama vs vLLM When to Scale Up
We chose Ollama because this is a single-developer workstation. Ollama wins on simplicity, resource efficiency, and single-user performance. One curl to install, one command to pull models, and it just works.
The tradeoff: if you later need to serve multiple concurrent Coder workspaces (5+ users hitting the same GPU), vLLM delivers roughly 16x more throughput under concurrent load. That's a future upgrade path, not a day-one requirement.
<CollapsibleCode label="vLLM upgrade command (for future multi-user)">
```bash
docker run --rm -it --gpus all --ipc=host --network host \
-v ~/.cache/huggingface:/root/.cache/huggingface \
nvcr.io/nvidia/vllm:26.01-py3 \
vllm serve "Qwen/Qwen3-Coder-Next-FP8" \
--served-model-name qwen3-coder-next \
--port 8000 \
--max-model-len 170000 \
--gpu-memory-utilization 0.90 \
--enable-auto-tool-choice \
--enable-prefix-caching \
--kv-cache-dtype fp8
```
</CollapsibleCode>
## Gotchas
1. **Registry names lie.** `devstral-small:24b` is what guides reference. `devstral` is what Ollama's registry actually has. Always check `ollama search` or the Ollama website before assuming a model name.
2. **Cold starts kill scripted tests.** Loading 23 GB into VRAM takes real time. If you're capturing output in a bash script with `$()`, the command can return before the model finishes loading. Manual `ollama run` works fine because it waits interactively.
3. **`KEEP_ALIVE` is essential.** The default 5-minute unload timer means constant cold starts during normal coding. Set it to `30m` or `-1` (indefinite) via the systemd override. This is the single biggest quality-of-life improvement.
4. **60 GB != 64 GB is normal.** The kernel and firmware reserve memory. Your 64 GB kit will report ~60 GB usable. This is expected, not a hardware problem.
5. **Coder requires an API key even when the provider doesn't.** Ollama doesn't authenticate requests, but Coder's provider config won't save without a key. Use any placeholder string. `ollama` works.
6. **Model identifiers must be exact.** The string you enter in Coder's admin panel is sent verbatim to the `/v1/chat/completions` endpoint. If you type `qwen3.5:35b-a3b` but Ollama expects `qwen3:35b-a3b`, you'll get a model-not-found error. Run `ollama list` and copy the name exactly.
## What's Next
The models are running locally and wired into Coder Agents. We have a fully self-hosted AI coding environment: Coder server, Ollama, and local inference on the same box, with cloud providers as a fallback.
The next step is benchmarking. How many tokens per second does `qwen3.5:35b-a3b` actually push on this hardware? Is the 256K context window usable in practice, or does performance degrade at long contexts? Does `codestral:22b` autocomplete feel instant in the IDE, or is there noticeable lag? And the real question: for which tasks do local models match cloud providers, and where do they fall short?
Numbers coming soon.
## By the Numbers
- 1 Ollama install (v0.21.0, single curl command)
- 5 models pulled (4 generation + 1 embedding)
- ~44 GB total model storage
- 32,607 MiB VRAM available
- 2 models configured in Coder Agents (Qwen 3.5B + Devstral)
- 1 model name that was wrong (`devstral-small:24b` -> `devstral`)
- 1 cold-start timing bug in the verification script
- 15 minutes from script start to working local inference
- 0 cloud API calls required
- 0 data leaving the network
===
## From Idea to Infrastructure: Standing Up a Self-Hosted AI Dev Environment
- URL: https://vibescoder.dev/posts/from-idea-to-infrastructure-standing-up-a-self-hosted-ai-dev-environment
- Date: 2026-04-21
- Tags: #coder #agents #homelab
- Reading time: 10 min read
The journey from "I should build a home lab" to a fully configured self-hosted Coder server with GitHub integration, multi-user workspaces, and AI agents that actually know how to use the tools available to them.
---
The first wave of content here on Vibes Coder was meta by design: a blog about building a blog, from a cabana in Cabo, on an iPhone. But that was always just the foundation. The thing I actually want to explore is local and self-hosted AI, and that starts with infrastructure.
This post is the journey from "I should build a home lab" to a fully running Coder server with GitHub integration, workspace templates, multi-user support, and AI agents that are genuinely useful out of the box. Everything here was done conversationally through [Coder Agents](https://coder.com/agents).
## Why Self-Hosted Why Now
We're in the middle of an explosion in local hardware capabilities. Apple's shipped insanely powerful M-series silicon for generations. Qualcomm's latest Snapdragon Elite processors are serious. NVIDIA keeps pushing consumer GPUs with more VRAM, and is now getting into CPUs with the N1 chips. The combination of CPUs, GPUs, and NPUs available today far exceeds what standard productivity apps actually require.
It's pretty clear where this is heading: sophisticated LLMs running directly on our devices. I genuinely believe the future is Siri interfacing with a local model on an iPhone. A self-hosted home lab is the best approximation for testing that future before on-device capabilities go mainstream.
So I broke this into three phases:
1. **Get the hardware** capable of real inference
2. **Build the dev environment** to work with it (Coder, agents, templates)
3. **Run local models** and wire them into the coding workflow
This post covers phases 1 and 2. Phase 3 posts next.
## The Hardware Hack Buy a Gaming PC
How do you get a machine powerful enough for serious AI work when RAM, storage, and GPU prices are brutal?
**Buy a pre-built gaming PC.**
Individually sourcing components means paying extreme markups, thanks to AI's ripple effects on GPUs, memory, and storage. But a gaming PCs built a few months ago with all the latest parts are just sitting on shelves at Best Buy, Newegg, and Micro Center. These complete systems are actually worth more parted out than what they're selling for. The pricing is inverted.
I picked up a rig from Newegg. Here's what's inside:
| Category | Component | Spec |
|---|---|---|
| CPU | AMD Ryzen 9 9950X3D | 16-core Zen 5, 5.75 GHz boost |
| GPU | Zotac RTX 5090 | **32 GB GDDR7** |
| RAM | G.Skill Trident Z5 RGB | 64 GB (2x32 GB) DDR5-6000 |
| Storage | Samsung 9100 Pro | 2 TB Gen5 NVMe |
| PSU | Thermaltake Toughpower GT | 1200W 80+ Gold ATX 3.1 |
| OS | Ubuntu 24.04 LTS | NVIDIA driver 590.48.01 |
The spec that matters most for local LLMs is VRAM. The 32 GB on the RTX 5090 is the sweet spot: enough to run 27B-35B parameter models at full quality, or 70B models at aggressive quantization. The 64 GB system RAM provides headroom for KV cache spillover, and the 2 TB NVMe means models load fast and you can store plenty without worry. More on all of that in the next post. Now I have a capable AI workstation, in all it's RGB puke glory.
But a powerful machine sitting in a closet isn't useful until you can actually develop on it. That's where Coder comes in.
## Standing up Coder
I installed Ubuntu on the workstation. Why Ubuntu? It has the most documentation and is often what surfaces first in searches. Basically, it's the most agent-friendly distro. I didn't want troubleshooting my deployment with an agent to conflate Mint or Pop!_OS solutions. This was pretty straight forward minus a snafu getting the RTX 5090 drivers. Ends up you have to the install the open ones, and not the NVIDIA proprietary ones. Thankfully my motherboard had a built-in HDMI port I could use with the Ryzen's iGPU.
15 minutes later I connected my Ubuntu workstation via a Coder tunnel. This gives me a full cloud development environment accessible from anywhere, including my phone. Workspaces run as Docker containers on the machine, each with its own isolated environment, tools, and credentials.
The goal: anyone who creates a workspace from the template gets GitHub access, a full toolchain, and AI agents that know how to use everything, automatically. No manual setup.
### GitHub Auth the Long Way Around
The first task was connecting Coder workspaces to GitHub so agents could clone repos, commit, push, and create PRs without manual token management.
I explored three options:
- **Personal Access Tokens** — works but doesn't scale to multiple users
- **SSH keys** — same problem
- **Coder External Auth (OAuth)** — configure once on the server, every user authenticates through the browser with their own GitHub account
Chose option 3. Created a GitHub OAuth App, configured the callback URLs, and started fighting with the server configuration.
**The first struggle**: Coder wasn't running in Docker (just using Docker for workspaces). It was running as a manual `coder server` process. The config file at `/etc/coder.d/coder.env` existed but wasn't being loaded because the file uses `VAR=value` format without `export`, and `source` reads the file but doesn't export to child processes. Had to `export` the variables directly in the shell before running the server.
**The plot twist**: After all the OAuth App setup, I discovered the Coder version had a **built-in default GitHub provider** that was already enabled. Navigating to `/external-auth/github` just worked. Didn't even need the custom OAuth App.
**Lesson**: Check `coder server --help` before manually configuring things. Or, realistically, ask your agent to do it for you. The answer was in the flags the whole time.
### Wiring GitHub into the Workspace Template
Even after authenticating, workspaces didn't automatically have GitHub credentials available. The external auth token existed but nothing told `git` or `gh` to use it.
The fix was template changes to `main.tf`:
```hcl
data "coder_external_auth" "github" {
id = "github"
}
```
Plus injecting `GITHUB_TOKEN` into the agent's environment variables and adding a startup script that configures the git credential helper and installs the GitHub CLI.
The template workflow I learned:
```bash
mkdir -p ~/coder-templates/docker
cd ~/coder-templates/docker
coder templates pull docker .
# edit main.tf
coder templates push docker
coder update my-workspace # critical — stop/start alone reuses the old version
```
That last line is a gotcha worth highlighting: **stopping and starting a workspace doesn't update the template version.** You must run `coder update` to apply new template changes to an existing workspace.
### System Instructions That Actually Work
With GitHub fully wired up, agents still had a problem: they'd ask users to authenticate or provide tokens. They didn't know the environment was pre-configured.
The fix was adding system instructions in the Coder admin panel (Agents > Settings > Behavior) that apply to all users. The key points:
- GitHub access is pre-configured. Never ask users to authenticate.
- Use `gh` CLI for all GitHub operations.
- Always commit and push. Workspaces are ephemeral; GitHub is the source of truth.
- Bias toward action. Build first, ask questions only when genuinely ambiguous.
- Do the full loop: write code, install deps, test, commit, push.
- Install tools with `sudo` as needed without asking permission.
- Don't ask "would you like me to..." for obvious next steps.
This is the difference between an agent that's technically capable and one that's actually useful. Without these instructions, every session started with five minutes of the agent asking permission to do things it already had access to do.
### The Vibe Coding Toolchain
The base Docker image was missing most of what a modern coding session needs. Added to the startup script:
| Tool | Why |
|------|-----|
| GitHub CLI (`gh`) | Repo management, PRs, issues from the terminal |
| Node.js + npm | Most web projects need it |
| Vercel CLI | Deploy directly from the workspace |
| uv | Fast Python package manager for new projects |
| zip, unzip, sqlite3 | Common utilities that were missing |
All installs are idempotent (`if ! command -v ... &> /dev/null`) so they only run on first boot.
### Multi-User Setup
The real test: could my partner use the same server with her own account and GitHub credentials?
Setup was three steps:
1. `coder users create` on the host
2. She logs in, creates a workspace from the Docker template
3. Visits `/external-auth/github` once to link her GitHub account
Everything else (gh, git credentials, Vercel, system instructions) was automatic from the template. That's the whole point of doing this at the template level rather than per-workspace.
## The Architecture
Here's what we ended up with:
```
Ubuntu AI Workstation (home lab)
├── coder server (running via tunnel)
│ ├── Built-in GitHub OAuth provider
│ ├── Agents with system instructions
│ └── Docker template
│ ├── GITHUB_TOKEN auto-injected per user
│ ├── gh CLI pre-installed
│ ├── Node.js + npm + Vercel CLI
│ ├── Python 3.12 + uv
│ └── code-server (VS Code in browser)
├── Docker (runs workspace containers)
└── Coder tunnel (*.try.coder.app)
```
Every user gets their own isolated workspace with full GitHub integration, a complete toolchain, and AI agents that know how to use all of it. The server handles auth, templates handle environment setup, and system instructions handle agent behavior.
## Gotchas Worth Knowing
A few things that cost us time:
1. **`source` vs `export`**: `source /etc/coder.d/coder.env` reads the file but doesn't export variables to child processes. If your env file doesn't use `export` statements, child processes (like `coder server`) won't see the values.
2. **Template versioning**: Stopping and starting a workspace reuses the old template version. You must run `coder update <workspace>` to pick up new template changes. This one bit us three times before it stuck.
3. **Agents settings vs Deployment settings**: They're in completely different places in the Coder UI. Agents settings control AI behavior; deployment settings control server config. Easy to confuse.
4. **The built-in GitHub provider**: We spent time creating a custom OAuth App before discovering Coder ships with a default GitHub provider that was already enabled. The `--help` output had the answer all along.
5. **Agent session refresh**: After template changes that modify environment variables, you need a fresh Agents session. The running session won't pick up the new values.
## What's Next Local LLMs
The hardware is ready. The dev environment is running. But right now, all the AI work is still going through cloud APIs: Claude for blog generation, Claude for coding agents.
Tomorrow, we change that.
The RTX 5090's 32 GB of VRAM is sitting idle, and there's an entire ecosystem of open-source models that can run locally on this hardware. We're going to install Ollama, pull a stack of models purpose-built for different coding tasks, and start wiring local inference into the development workflow.
If you've ever wondered what it takes to run a 35-billion-parameter model on consumer hardware, or whether local models can actually keep up with cloud APIs for real coding work, that's what we're testing next.
## By the Numbers
- 1 gaming PC purchased from Newegg
- 1 Coder server running via tunnel
- 1 GitHub OAuth integration (built-in, no custom app needed)
- 1 workspace template with 6 pre-installed tools
- 2 users configured
- 3 template pushes to get everything right
- ~15 minutes debugging `export` vs `source`
- 0 lines of code written outside of Coder Agents
- 32 GB of VRAM waiting for local models
===
## Open-Sourcing a Blog Without Open-Sourcing Your Drafts
- URL: https://vibescoder.dev/posts/open-sourcing-a-blog-without-open-sourcing-your-drafts
- Date: 2026-04-20
- Tags: #agents #security
- Reading time: 6 min read
I open-sourced my blog for Giscus comments and immediately found a gutted .gitignore, an exposed server URL, and all my unpublished drafts on GitHub. Here's how I split code from content without changing a single line of application code.
---
I open-sourced my personal blog repo so I could use [Giscus](https://giscus.app) for blog comments — it needs a public repo with GitHub Discussions enabled. But open-sourcing the repo meant *everything* was public: unpublished drafts, raw session notes, half-baked ideas, and my TODO list. For a thought leadership blog, that's a problem. People could just read GitHub instead of the site.
Before we even got to that realization, though, we found something worse.
All of the work in this session was done conversationally through [Coder Agents](https://coder.com/agents) on a self-hosted home lab setup. (You'll hear a lot more about that setup soon — I'll be writing about the full home lab build next.)
## The Security Audit
First thing we did was scan the repo for anything sensitive now that it was public. Found three issues.
### 1 the .gitignore Was Gone
In a previous session, an agent had tried to set up a drafts workflow. The idea was to use `.gitignore` to keep drafts out of the repo. When that broke persistence (gitignored files don't survive workspace destruction), I asked the agent to fix it. Instead of removing the one `blog-drafts/` line, it replaced the entire `.gitignore` with a single comment — deleting all 50 standard Next.js ignore patterns.
This meant `.env`, `.env.local`, `node_modules/`, `.next/`, `.vercel/`, `*.pem` — none of it was being ignored. If anyone (or any agent) had run `git add .`, every secret in `.env` would have been committed to a public repo.
**The root cause**: The agent conflated two separate concerns — git tracking (persistence) and site publishing (visibility). `.gitignore` controls what git tracks, not what the site renders. The blog already had `published: false` frontmatter support in `posts.ts` that filters unpublished posts from the public site. The agent didn't look at existing code before reaching for a filesystem-level solution.
**Lesson**: When an AI agent suggests a fix, check whether the codebase already solves the problem. Also, always diff what an agent changed — don't assume a targeted edit was actually targeted.
### 2 Live Server URL Exposed
The blog drafts contained my actual Coder server tunnel URL — a live endpoint to my self-hosted instance sitting in the blog fodder notes from a previous session. Anyone could have tried to hit it.
**Fix**: Replaced with a placeholder and rotated the URL.
### 3 Infrastructure Reconnaissance
The drafts also contained hardware specs, home lab architecture details, systemd config paths, and multi-user setup info. Not a vulnerability per se, but useful reconnaissance for someone targeting the setup.
**Verdict**: Acceptable for a "building in public" blog, but worth being aware of.
## The Real Problem Code Vs. Content Visibility
After fixing the immediate issues, we hit the bigger question: what about a world where this is a well-trafficked site? Anyone could ignore the site entirely and browse GitHub for unpublished drafts, upcoming topics, and editorial strategy.
`published: false` only gates the rendered site. GitHub shows everything.
### Why Not Just Make the Repo Private
Giscus. The whole reason we open-sourced was for blog comments. Giscus requires a public repo with GitHub Discussions enabled. Making the repo private kills comments.
### The Key Insight
Giscus doesn't care what's *in* the repo — it just needs a public repo to host GitHub Discussions. The discussions are completely independent of the repo's file contents. So we could separate the code from the content without touching Giscus at all.
## The Solution Two Repos
**`the-vibe-coder`** (public) — The blog engine. All source code, configs, components, API routes. Giscus stays pointed here. Open source, as intended.
**`the-vibe-coder-content`** (private) — All content: published posts, unpublished drafts, raw session notes, settings, images, TODO list. Nobody sees this but me.
### How They Connect
The critical design decision: the private repo uses the **exact same directory structure** as the original. This meant zero code changes to the GitHub API client, the post loader, or any admin panel routes. The only change was pointing the `GITHUB_REPO` environment variable at the private repo.
A prebuild script clones the private repo at build time and overlays the content into the working tree. On Vercel, this runs automatically before `next build`. Locally, you clone the content repo once and copy or symlink.
### The Deploy Hook
Since Vercel watches the public code repo, it wouldn't know to rebuild when content changes in the private repo. A GitHub Action on the private repo hits a Vercel Deploy Hook on every push to main:
Content commit → GitHub Action → Vercel rebuild → site updated.
## The Wiring
1. Created the private content repo
2. Pushed all content files (same directory structure)
3. Added a `fetch-content.sh` prebuild script to the public repo
4. Updated `.gitignore` to exclude content directories
5. Removed content files from the public repo
6. Updated `GITHUB_REPO` on Vercel to point to private repo
7. Created a Vercel Deploy Hook + GitHub Action trigger
### The Token Gotcha
First deploy failed with exit code 128 (git auth failure). The `GITHUB_TOKEN` was a fine-grained PAT scoped to only the original repo. Had to update it in GitHub to also include the new private repo. Fine-grained PATs don't automatically pick up new repos — if your build pipeline uses one and you add a new private repo, you'll get a 403 until you update the token's repo list.
## What I Learned
### Agents and .gitignore
Agents reach for `.gitignore` as a blunt instrument. When the problem is "don't show this on the site," the answer is almost never "don't track it in git." Those are different concerns:
- **Git tracking** = persistence, collaboration, backup
- **Site publishing** = what visitors see
Conflating them leads to either lost work (gitignored files vanish) or the opposite — a gutted `.gitignore` that exposes secrets.
### Always Audit Before Open-Sourcing
We caught three issues in a five-minute scan. The `.gitignore` one was a genuine time bomb. Open sourcing without a security pass is shipping without testing.
### Giscus Is Decoupled from Content
This was the unlock. You can have a public repo with zero content files and Giscus works perfectly. "I need Giscus" and "I need private content" aren't in conflict.
### The Same-Structure Trick
By keeping the private repo's directory layout identical to the original, we avoided code changes entirely. The admin panel, the build process, and the content API all work unchanged — they just talk to a different repo via the same env var. This is the kind of thing that makes a migration smooth instead of a refactor.
## By the Numbers
- 1 `.gitignore` restored from 1 line to 52 lines
- 1 server URL redacted and rotated
- 2 repos (1 public, 1 private)
- 0 code changes to the blog engine
- 1 prebuild script (24 lines of bash)
- 1 GitHub Action (8 lines of YAML)
- 1 Vercel Deploy Hook
- 1 fine-grained PAT updated
- 5 published posts confirmed rendering
- 1 unpublished draft confirmed hidden
- ~45 minutes from "is there anything sensitive?" to verified deploy
===
## Day 5: Week 1 Challenge Complete!
- URL: https://vibescoder.dev/posts/week-one-complete-building-a-personal-blog-from-a-cabana-in-cabo
- Date: 2026-04-18
- Tags: #next-js
- Reading time: 9 min read
Adding a commenting system with Giscus, cleaning up the repo for public release, researching Whisper vs Wispr, and closing out week one — all from a cabana in Cabo.
---
## Week One That's a Wrap
And that's a wrap on week one.
I set myself a challenge: could I build a working personal website in five days, spending 60–90 minutes each day, using nothing but my iPhone, all while lounging in a cabana in Cabo?
**The answer? Absolutely.**
- **Timeline**: 5 days
- **Daily commitment**: 60–90 minutes
- **Device**: iPhone only
- **Location**: Cabana in Cabo (because why not mix work with paradise?)
- **Goal**: A functioning personal blog to catalog my journey through AI technologies
The blog is live, has an admin dashboard, voice-to-post pipeline, RSS, analytics, syndication, and — as of today — a commenting system and a public GitHub repo. There's something satisfying about proving you don't need a fancy setup or hours of uninterrupted coding time to ship something meaningful.
But Day 5 wasn't about adding flashy features. It was about polish, research, and getting the house in order before opening the doors.
## Blog Comments with Giscus
Every blog needs a way for readers to respond. The question was which commenting system to use. Disqus is bloated and ad-heavy. A custom solution with Upstash would mean building auth, moderation, and spam filtering from scratch. Since all the blog content already lives on GitHub, **Giscus** — a commenting system powered by GitHub Discussions — was the natural fit.
Giscus works by mapping each blog post to a GitHub Discussion thread. Readers sign in with their GitHub account to comment. No database, no third-party data, no ads. Comments live right in the repo's Discussions tab.
The implementation is a React component that watches the site's `data-theme` attribute and syncs the Giscus iframe theme in real time. Toggle from dark to light mode, and the comments follow instantly — no page reload.
<PhoneScreenshots caption="Configuring Giscus on my phone — mapping, category, and feature settings">
<PhoneScreenshotItem src="/images/day-five/IMG_9136.png" alt="Giscus configuration page showing discussion mapping options with pathname selected" />
<PhoneScreenshotItem src="/images/day-five/IMG_9138.png" alt="Giscus category set to Announcements with feature checkboxes" />
</PhoneScreenshots>
There was a catch: Giscus requires a **public** repository. Ours was private. That single requirement kicked off the most interesting part of Day 5.
<PhoneScreenshots caption="Selecting the theme and getting the final embed snippet">
<PhoneScreenshotItem src="/images/day-five/IMG_9140.png" alt="Giscus theme dropdown showing available theme options" />
<PhoneScreenshotItem src="/images/day-five/IMG_9142.png" alt="Generated Giscus script tag with all configuration values" />
</PhoneScreenshots>
## Opening the Repo Security First
Making a repo public isn't something you do casually. If there's a hardcoded API key or a GPS-tagged photo buried in the history, you've got a problem. So before flipping the switch, I had the agent run a full security assessment.
**What it checked:**
- Every source file for hardcoded secrets, API keys, tokens, and passwords
- Git history for any commits that might have added and later removed sensitive data
- Image EXIF metadata for GPS coordinates or device information
- All environment variable references to verify nothing was hardcoded
- Blog post content for accidental inclusion of credentials
- npm dependencies for known vulnerabilities
- Next.js configuration for exposed server-side values
**The result: clean bill of health.** All credentials were properly environment-variable'd. The git history even showed a prior commit that proactively scrubbed sensitive info. Zero npm audit vulnerabilities. No EXIF data risk on the images.
But "secure" isn't the same as "presentable."
## The Cleanup Pass
I want a site my software engineers respect. Ok, maybe that’s too high a bar. How about: They don’t dismiss a slop.
It needed to be well-organized, no dead code, no leftover boilerplate from `create-next-app`.
The agent audited every file in the project. Here's what we found and cleaned up:
**Removed — dead code and artifacts:**
- 5 unused Next.js boilerplate SVGs (`next.svg`, `vercel.svg`, `globe.svg`, `file.svg`, `window.svg`) — default files from project scaffolding that were never referenced
- A 1.8 MB Stitch design ZIP from Day 2 — the design artifact that generated our theme, but doesn't belong in a source repo
- `/api/transcribe` — a 501 stub route we'd reserved for Whisper integration (more on that below)
- `/api/auth/status` and `/api/posts/list` — two API endpoints that existed but were never called by any frontend code
- `content/day-3-prompt.md` — session notes used to generate the Day 3 blog post
- `pnpm-lock.yaml` and `pnpm-workspace.yaml` — the repo uses npm, but these pnpm files were lingering from early setup, creating a confusing mixed-package-manager signal
**Added:**
- `.env.example` documenting all 8 required and optional environment variables
- A rewritten `README.md` with project structure, tech stack table, setup instructions, and the voice-first workflow explanation
**Kept intentionally:**
- `/api/settings` — the backend for a future admin settings page. The API is functional, the UI isn't built yet. Dormant, not dead.
The final diff: 22 files changed, net reduction, zero build errors. The kind of commit that makes a repo feel maintained rather than abandoned.
## The Coder.com Blog Investigation
One item on the punchlist was adding author filtering to the Coder company blog. The idea: a footer link on vibescoder.dev that goes directly to my posts on coder.com/blog.
This turned out to be a research task, not a coding task. The Coder company blog lives in a separate repo (`coder/coder.com`), uses DatoCMS for content management, and Algolia for search. Authors exist in the CMS — there's a full `CMSAuthor` interface with aliases, bios, photos, and social links. And there's already category filtering via `?category=...` query parameters using Algolia facets.
**But there's no author filtering.** No `?author=rob` parameter, no clickable author links, no author facet in Algolia. The infrastructure is 80% there — it just needs someone to wire up the last mile, mirroring the existing category filter pattern.
Rather than build it myself in a repo I don't own, I filed [an issue](https://github.com/coder/coder.com/issues/719) with the full implementation path. The coder.com team can prioritize it from there.
## The Whisper / Wispr Mix-Up
This is my favorite moment from Day 5.
My CEO friends have been raving about "Whisper" for months. I had it on my to-do list: "Explore Whisper integration — evaluate for transcription pipeline." I assumed it was something we should build into the site.
So the agent started researching **OpenAI Whisper** — an open-source speech recognition model that OpenAI built and released in September 2022. It's trained on 680,000 hours of audio data, costs $0.006 per minute via API, and is genuinely impressive for transcription accuracy with accents and technical jargon.
But here's the thing: we already have client-side transcription via the Web Speech API. It's free, it's real-time, and it works great for the "talk into your phone → blog post" pipeline. Whisper would be a lateral move for that use case — same job, costs money, adds latency.
Then I realized: my friends aren't talking about OpenAI Whisper. They're talking about **Wispr Flow** (wisprflow.ai) — a completely different product by a completely different company.
**OpenAI Whisper**: An open-source ML model for speech recognition. No app. A developer tool.
**Wispr Flow**: A $700M-valued AI dictation app that works as a system-level voice keyboard across Mac, Windows, iOS, and Android. You activate it with a key press, speak naturally, and it inserts formatted text wherever your cursor is.
They just happen to have almost identical names. So, side note: Ask people to spell tech when discussing it at a networking event.
Here's the punchline: **there's nothing to integrate.** Wispr Flow already works with any text field on any website — including our admin pages. If I install the app, I can use it to dictate into the blog's transcript editor right now. No code changes needed.
The "Whisper integration" to-do item was based on a naming confusion. Researched, understood, dismissed. But it makes for a good story about the importance of actually understanding what you're evaluating before you build it.
## The Small Fixes
A few quality-of-life improvements rounded out the session:
**PostCard click targets**: The homepage post cards had a full-card link behind the content, but the text, description, and date elements at `z-10` were intercepting clicks. Added `pointer-events-none` to the non-interactive content so clicks pass through to the underlying link, while keeping tags and admin controls independently clickable.
**About page refresh**: Rewrote the intro section with a personal photo and actual context — CEO of Coder, the voice-first development experiment, what the blog is really about after four days of building. Kept "The Setup" section as-is.
**Footer wrapping**: "Company Blog" was line-wrapping on mobile in the footer nav. Shortened to "Blog." Sometimes the best fix is the smallest one.
## What I Learned
**Security assessments before going public are non-negotiable.** Even when you're pretty sure the repo is clean, "pretty sure" isn't good enough. A systematic scan of every file, the git history, image metadata, and dependency vulnerabilities takes minutes and eliminates the category of risk entirely.
**Clean repos are a form of communication.** Removing five boilerplate SVGs doesn't change how the site works. But it signals that someone is maintaining this project with intention. When you're building in public, the repo *is* the resume.
**Name confusion is real.** I spent mental energy for weeks assuming "Whisper" was a product I needed to integrate. Five minutes of research revealed it was a completely different thing from what my friends were using. The lesson: when someone recommends a tool, ask for the URL, not just the name.
**Building in public means shipping imperfect.** The Giscus comments went live before I had the perfect category ID. The About page went up before I had the perfect bio. The repo went public before I had the perfect README. You iterate in public or you never ship.
## This Is Just the Beginning
The blog is live and functional. But this was always just the foundation. I've got my eyes on a bigger project — one that uses everything I've learned about AI-native development, governed cloud agents, and vibe coding on the go. Next up? Self-hosting the entire stack. Stay tuned.
For now, I'm going to enjoy the fact that I shipped a working blog while sipping drinks in paradise. Sometimes the best coding sessions happen in the most unexpected places.
---
## By the Numbers
- **1 commenting system** added (Giscus via GitHub Discussions)
- **1 repo** made public after security audit
- **1 issue filed** on coder/coder.com for author filtering
- **1 About page** rewritten with photo and bio
- **1 naming confusion** resolved (Whisper ≠ Wispr)
- **7 files removed** (dead code, boilerplate, artifacts)
- **2 files added** (.env.example, GiscusComments component)
- **22 files changed** in the cleanup commit
- **1.8 MB** of design artifacts removed from the repo
- **0 security issues** found in the audit
- **5 days**, **1 iPhone**, **1 cabana** — blog complete
===
## Day 4: RSS, Analytics, Syndication, and the Loom Pipeline
- URL: https://vibescoder.dev/posts/day-four-rss-analytics-syndication-and-loom
- Date: 2026-04-17
- Tags: #next-js #agents
- Reading time: 11 min read
Adding an RSS feed, wiring up analytics with an in-admin chart, discovering Medium locked their API, pivoting to Dev.to, and laying the groundwork for Loom-powered blog generation.
---
## The Distribution Problem
Days 1 through 3 built a blog I could write on. Day 4 is about making sure anyone can actually find it.
A personal blog with no RSS feed, no analytics, and no presence on any platform is a journal, not a publication. This session adds the plumbing that turns content into reach: a way for readers to subscribe, a way for me to see who's reading, a way to cross-post to larger platforms, and a new content format that leads with video.
The scope for today: RSS feed, analytics with an in-admin chart, syndication to a developer platform, and a Loom video embed component. Four features, one session, all from my phone — with the AI agent spawning parallel workers to build independent features simultaneously.
<PhoneScreenshot src="/images/day-four/coder-agents-spawning.png" alt="Coder agent spawning parallel workers for RSS, Loom, and analytics features" caption="Four features built in parallel — the agent splits independent work across sub-agents" />
## RSS Feed
The simplest feature with the longest history. RSS is 25 years old and still the best way to let readers follow a blog without handing over an email address.
The implementation is a single Next.js route handler at `/feed.xml`. It reads all published posts via the same `getAllPosts()` function that powers the homepage, then templates them into RSS 2.0 XML with proper RFC 822 dates, GUID links, and category tags.
Three additions total:
1. **`src/app/feed.xml/route.ts`** — the route handler
2. **RSS autodiscovery link** in `<head>` — so feed readers find it automatically
3. **RSS link in the footer** — so humans find it too
No dependencies. RSS XML is simple enough to template as a string.
## Analytics Two Layers
I wanted analytics I could see without leaving my admin dashboard. That turned out to require two separate systems.
### Layer 1 Vercel Web Analytics
Vercel offers built-in web analytics on the free Hobby plan. Setup is two lines: install `@vercel/analytics`, add `<Analytics />` to the root layout. Privacy-friendly — no cookies, just a hashed identifier that resets daily.
<PhoneScreenshot src="/images/day-four/vercel-analytics-setup.png" alt="Vercel Analytics setup page showing install steps" caption="Vercel walks you through it — but both steps were already done by the agent" />
**The catch:** Vercel Web Analytics has no REST API. There's no way to query the data programmatically. You can see it in the Vercel dashboard, but you can't pull it into your own UI.
### Layer 2 Custom View Counter with Upstash Redis
So we built our own. A `PageViewTracker` component fires a POST on every page load. An API route increments counters in Upstash Redis. An admin endpoint returns the last 30 days of data.
**Why Redis?** We're incrementing simple counters — `views:2026-04-17:total` — thousands of times a day. Redis is purpose-built for this: in-memory key-value store, atomic increments in microseconds. Postgres would be overkill for counting page views. Upstash's free tier (10K commands/day) is more than enough for a personal blog.
<PhoneScreenshots caption="Choosing Upstash Redis from Vercel's storage marketplace">
<PhoneScreenshotItem src="/images/day-four/upstash-storage-picker.png" alt="Vercel storage picker with Upstash for Redis selected" />
<PhoneScreenshotItem src="/images/day-four/upstash-config.png" alt="Upstash Redis configuration — region, plan, eviction settings" />
</PhoneScreenshots>
One detail worth noting: when connecting the database to your project, Vercel suggests a "Custom Prefix" for the environment variables. The default was `STORAGE`, which would have created `STORAGE_URL` and `STORAGE_TOKEN`. Our code expects `KV_REST_API_URL` and `KV_REST_API_TOKEN` — so the prefix needed to be changed to `KV_REST_API` before connecting.
<PhoneScreenshot src="/images/day-four/upstash-project-connect.png" alt="Connecting Upstash to the Vercel project with environment prefix settings" caption="The env var prefix matters — it has to match what the code reads" />
The admin dashboard renders the analytics data as a CSS-only bar chart — no charting library, just calculated heights and the site's design tokens.
<PhoneScreenshot src="/images/day-four/analytics-dashboard.png" alt="Admin dashboard showing analytics chart with 14 views over 30 days and top pages" caption="The analytics chart, live with real data — 14 views and counting" />
## The Syndication Saga Medium → Dev.to
This is the story I didn't expect to be writing.
### The Plan Medium
The original plan was Medium. It has the largest general audience for developer content, supports markdown via API, and lets you set a `canonicalUrl` pointing back to your own site for SEO credit. We built the full integration: an API route that reads a post, strips frontmatter, and publishes to Medium as a draft. One-click syndication from the admin bar.
### The Discovery Medium Locked the Door
When I went to generate an integration token in Medium's settings, the option wasn't there.
<PhoneScreenshot src="/images/day-four/medium-no-token.png" alt="Medium settings page showing no integration tokens option" caption="Medium's Security and apps settings — no integration tokens anywhere" />
After some research: **Medium stopped issuing new integration tokens as of January 2025.** Existing tokens still work, but new accounts can't get one. The API docs repo was archived in March 2023. Medium wants content *in* but doesn't want developers building *on* their platform anymore.
We built the syndication, then discovered the platform locked the door.
### The Pivot Dev.to
After researching alternatives — Dev.to, Hashnode, Hackernoon, DZone — Dev.to was the clear winner:
- **Open API** with free API keys (generated in settings, takes 10 seconds)
- **Markdown-native** with syntax highlighting — perfect for a technical blog
- **Canonical URL support** — SEO credit stays with the original
- **Large developer community** — articles can reach tens of thousands of readers
- **No paywall** — readers see your content without friction
- **Draft mode** — review before publishing
<PhoneScreenshot src="/images/day-four/devto-api-key.png" alt="Dev.to API key generation page" caption="Dev.to gives you an API key in 10 seconds — no approval process, no OAuth dance" />
[Note: Want proof this is authentic? I kept the Google Home notification in my screenshot. That's my cameras picking up my cat, Snickers, back home. Don't forget, this is all from Cabo so far. If Snickers isn't zoombombing my meetings at home, he's notificationbombing my vibe coding. Cats gonna cat, amirite?]
The code swap took 15 minutes. Same architecture, different endpoint. The Dev.to API accepts `{ article: { title, body_markdown, canonical_url, tags, published } }` with an `api-key` header. One env var instead of two.
One gotcha: Dev.to tags can't contain hyphens. Our tags like `next-js` and `building-in-public` had to be sanitized — stripped to `nextjs` and `buildinginpublic`. A `.replace(/[^a-z0-9]/gi, "")` in the API route handles it.
<PhoneScreenshot src="/images/day-four/devto-syndication-success.png" alt="Admin bar showing successful DEV.to syndication with draft URL" caption="One click, one draft — canonical URL pointing back to vibescoder.dev" />
### Why Not Substack
Substack has no official public API for publishing. Unofficial libraries exist but rely on scraping session cookies — fragile and arguably violates their terms of service. Substack does support importing via RSS feed (which we now have), but that's a one-time bulk import, not ongoing syndication.
### The Distribution Strategy
For maximum reach, the play is:
1. **Dev.to** — automated via API, one-click from admin bar
2. **Medium** — manual "Import a Story" from your post URL (still works, adds canonical automatically)
3. **Hackernoon** — manual submission for your best pieces (editorial review, but great Google ranking)
Your personal site is always the source of truth. Everything else is syndication with canonical links pointing home.
## Loom Video Embed
The immediate implementation is simple: add an optional `loomUrl` field to post frontmatter, and when present, render a responsive Loom video player as the hero element at the very top of the post.
```yaml
---
title: "My Post"
loomUrl: "https://loom.com/share/abc123"
---
```
### The Bigger Vision
The real power isn't just embedding videos — it's using them as a content source. Record a Loom video — screen share, talking head, whatever. Loom generates a transcript. Claude reads the transcript and generates a blog post with the video embedded at the top. The video is the hero content — readers can watch or read, their choice.
This makes the blog a dual-format publication. Some topics are better explained by showing your screen. Having both formats, generated from a single recording, is the kind of workflow that makes maintaining a blog sustainable.
The Loom-as-recording-source integration is queued for a future session. Today we laid the display foundation.
## What I Learned
**Vercel Analytics is great until you want your own dashboard.** The product is polished, free, and privacy-friendly. But the lack of a query API means you can't build on top of it. For anything beyond "go look at the Vercel dashboard," you need your own tracking. The two-layer approach — Vercel for the full dashboard, custom Redis for the in-app chart — gives you both without paying for either.
**Platform APIs reflect platform priorities.** Medium wants content in; they locked the API. Dev.to wants developers building on their platform; they give you a key in 10 seconds. RSS remains the universal fallback because it doesn't depend on any platform's willingness to cooperate.
**Build the syndication, then test the integration.** We built a complete Medium integration before discovering the API was locked. The good news: the architecture was clean enough that swapping to Dev.to took 15 minutes. The lesson: validate platform access before writing code. Or at least, architect so the platform is a swappable detail.
**Loom changes what "writing a blog post" means.** When your blog can start from a video recording, the barrier to publishing drops. You don't need to sit down and type — you can record your screen while debugging, narrate your thought process, and let the AI turn it into a written post with the video embedded. The blog becomes a byproduct of work you're already doing.
---
## Post-Session Update
After publishing and actually using everything above, a few things came up that were worth fixing in the same session. This is the building-in-public part — you ship, you use it, you find the friction.
### The 2025 Bug When AI Gets the Year Wrong
Every blog post on this site had the wrong year. Day 1 through Day 4 — all dated 2025 instead of 2026. The footer copyright said 2025 too.
The root cause: AI models have a training data bias toward 2025. The original Day 1 and Day 2 posts were authored with 2025 dates, and the agent writing Days 3 and 4 perpetuated it by following the existing convention rather than checking the server clock. Nobody caught it until a reader pointed it out.
The manual fix was easy — update four frontmatter dates and a footer string. The systemic fix was more interesting: we added a `fixDateYear()` function to the post API that runs on every create and update. If the frontmatter date's year is more than a year behind the server clock, it auto-corrects the year before committing. So even when an AI writes `date: '2025-04-17'`, it lands in GitHub as `2026-04-17`.
The voice recording → Claude generation pipeline was already safe — it uses `new Date()` from the server. This closes the gap for direct authoring and inline edits. If you're building with AI, validate your dates. The model's sense of "now" may not match yours.
### Image Upload in the Inline Editor
Adding screenshots to the Day 4 post required uploading images to GitHub via the web UI — a workflow that pulled me out of the editing flow entirely. That friction was enough to warrant building proper image upload directly into the inline editor.
Now when you're editing a post, there's an "Add Image" button in the toolbar. Tap it, pick a photo from your camera roll, and it uploads to `public/images/{slug}/` via the GitHub API and inserts the markdown reference at your cursor position. No context switching, no GitHub web UI.
### Clickable Post Cards
A reader told me she was tapping the post description on the homepage and nothing happened — only the title was linked. We made the entire card clickable using an absolute-positioned link layer behind the content, with tags and admin controls remaining independently clickable via z-index.
### Save Confirmation
The inline editor's save button worked but gave no visual feedback — you'd hit Save, see nothing, and wonder if it went through. Added a prominent confirmation banner: "✓ Saved — Committed to GitHub — Vercel will redeploy in a few seconds." It shows for 3.5 seconds before the page reloads with fresh content.
### Footer Contrast
The footer links were nearly invisible — too light against the background. Bumped from `text-outline-variant` to `text-on-surface-variant` for all links except Admin, which stays intentionally dim.
## By the Numbers
- **1 RSS feed** generated from existing post data
- **2 analytics layers** (Vercel dashboard + custom Redis chart)
- **2 syndication platforms** explored, 1 locked (Medium), 1 shipped (Dev.to)
- **1 video embed** component (Loom, hero placement)
- **1 image upload** feature added to the inline editor
- **1 PhoneScreenshot** MDX component for mobile screenshots
- **1 date auto-correction** guard in the post API
- **9 screenshots** embedded with purpose-built layout components
- **5 QoL fixes** (tags, admin bar, save confirmation, clickable cards, footer contrast)
- **4 wrong dates** caught and corrected across all posts
- **0 paid services** — everything runs on free tiers
===
## Day 3: Building the Editing Layer
- URL: https://vibescoder.dev/posts/day-three-admin-tooling-and-the-edit-pipeline
- Date: 2026-04-16
- Tags: #next-js
- Reading time: 8 min read
Fixing a silent login bug, building inline editing, overhauling the admin dashboard, and adding a public changelog — the session where the blog became a tool I actually want to use.
---
## The Problem with Day 2
Day 2 ended with a beautiful site. Neon Brutalist palette, light/dark toggle, design tokens wired up properly. It looked great. But I couldn't actually use it.
The admin login page accepted the correct password and then… nothing happened. No error, no redirect, no feedback. Just the same login form staring back at me. The edit button on posts linked to a recording page that ignored the fact that you were editing — it always started fresh. The admin dashboard had one big "Record" button and no way to find an existing post.
Day 3 was about turning a pretty blog into a functional one. Less visual, more plumbing. The kind of session where everything you build is invisible to readers but makes the difference between "I'll update that later" and actually updating it.
## The Silent Login Bug
This one was subtle. The login form called `fetch` to set a session cookie, then used Next.js `router.push("/admin")` to navigate. In the App Router, `router.push` is a soft navigation — it fetches a React Server Component payload over the wire and patches the DOM. No full page reload.
The problem: after `fetch` sets a cookie, a soft navigation can reuse a stale client-side cache or have the middleware redirect silently swallowed. The browser has the cookie, but the RSC request either doesn't send it or the middleware response gets eaten by the router. The user lands right back on `/admin/login` with zero feedback.
The fix is almost embarrassingly simple:
```javascript
// Before: soft navigation, cookie may not propagate
router.push("/admin")
// After: hard navigation, browser sends fresh cookies
window.location.href = "/admin"
```
Same fix for logout. `window.location.href` forces the browser to make a full request with the current cookie jar. It's the standard pattern for auth state transitions in Next.js App Router — any time cookies change, don't trust soft nav.
This is the kind of bug that doesn't show up in development. You're already authenticated, the cache is warm, everything works. It only bites you in production when a real user (me, from my phone) hits the cold path.
## Admin Access
Two small UX fixes while I was in the auth flow:
**Footer link.** Added a subtle "Admin" link in the site footer — dimmed by default, lights up on hover with the primary accent. No security implications; the middleware blocks everything without a valid JWT. But now I don't have to type `/admin` from memory on a phone keyboard.
**Visitor-friendly login page.** If a non-admin stumbles onto `/admin/login`, they now see "This area is for the site owner" with a "Back to the blog →" link instead of a bare password field. Small thing, but it's the difference between a page that looks broken and one that looks intentional.
## The Edit Pipeline
This was the biggest fix of the session. The blog had a voice recording feature from Day 1 — talk into the browser, Claude generates an MDX post, one-click publish to GitHub. But it was create-only. The "Edit" button on each post linked to `/admin/record?edit=slug`, and the record page completely ignored the query parameter. Every recording session created a new post.
The fix touched five files:
1. **Record page** reads `?edit=slug` via `useSearchParams` (wrapped in a Suspense boundary — App Router requires this for client-side search params)
2. **On mount in edit mode**, fetches the existing post content from the API
3. **Generation API** receives the existing content alongside the new transcript, so Claude merges rather than rewrites
4. **Publish call** uses `PUT` (update) instead of `POST` (create) when in edit mode
5. **PostPreview** locks the slug field and shows "Update on GitHub" instead of "Publish to GitHub"
The `useSearchParams` + Suspense requirement is a Next.js App Router detail worth calling out. Without the Suspense boundary, the page throws during static rendering because search params aren't available server-side. It's documented, but it's the kind of thing that bites you when you're porting a pattern from Pages Router.
Now the voice-to-blog pipeline works in both directions: create from scratch, or record additional context and merge it into an existing post. Same UI, same flow, different HTTP verb.
## Admin Dashboard Overhaul
The original admin dashboard had three cards: Record, Manage, Settings. Record was the only one that did anything useful. For Day 3, it became two distinct entry points:
**Record New Post** — same as before, links to `/admin/record` with no query params.
**Edit Existing Post** — a searchable dropdown picker. Type to filter posts by title (case-insensitive substring match), click to navigate to `/admin/record?edit=slug`. The dropdown is scrollable (`max-h-64`) and closes on click-outside via a `pointerdown` listener. Designed to handle hundreds of posts without pagination — client-side filtering is fine at blog scale.
## Inline Text Editing
The voice recording flow is great for substantial rewrites, but overkill for fixing a typo. So I added a third option: inline text editing directly on the blog post page.
The admin bar on each post (visible only when logged in) expanded from two actions to three:
| Action | What it does |
|--------|-------------|
| **Type Edits** | Opens a textarea with the raw MDX, right on the post page |
| **Record Edits** | Links to the voice recording flow for substantial changes |
| **Delete Post** | Removes the post from GitHub (moved to right side) |
The inline editor loads the raw MDX source, lets you edit in place, and saves via `PUT /api/posts`. No page navigation, no recording session, no Claude generation. Just fix the typo and hit Save.
This is the feature that changed how I use the site. Before, fixing a date typo meant opening the voice recorder, describing the change, waiting for Claude to regenerate, and publishing. Now it's: click Type Edits, fix the character, Save. Five seconds instead of two minutes.
## Public Changelog
Every edit should be transparent. I added a `changelog` field to the post frontmatter — an array of `{date, summary}` entries:
```yaml
changelog:
- date: '2026-04-16'
summary: Fixed Koto -> Coder typo
```
A collapsible `<Changelog>` component renders between the post header and content. Collapsed by default — "▸ 1 update" or "▸ N updates" — and expands on click to show the full history. Subtle monospace styling that doesn't compete with the post content.
The changelog entries are generated automatically based on the edit type:
- **Inline edits** get a summary derived from a line-level diff: "Minor text edits," "Edited N lines," or "Revised post content (N lines changed)" depending on scope
- **Voice recording edits** default to "Updated via voice recording"
- **Manual summaries** are still supported if you want to be specific
No AI needed for the diff summaries — just line counting. No commit SHAs, file paths, or system information exposed. Only reader-facing descriptions.
One gotcha: the initial changelog text used `text-outline-variant/60`, which was nearly invisible in light mode. Bumped to `text-on-surface-variant` for proper readability in both themes. Another reminder to test both modes after every UI change.
## The Blog Post Consolidation
A meta moment: during Day 3, I used the voice recording feature to publish a post about the Google Stitch workflow from Day 2. Then I realized it belonged in the Day 2 post, not as a standalone entry.
So I merged it — the brand guidelines trick and the mobile pipeline section got folded into the Day 2 post as new subsections, and the standalone third post got deleted. This is the kind of editorial decision that's easy when your content is just files in git. No CMS to wrestle with, no database records to reconcile. Delete a file, edit another file, push.
## What I Learned
**Soft navigation is not your friend during auth transitions.** Next.js App Router's `router.push` is a client-side RSC fetch. If you've just set or cleared a cookie, the soft navigation may not reflect that. Use `window.location.href` any time authentication state changes. This isn't a bug — it's a fundamental aspect of how RSC caching works.
**Build the editing tools early.** I should have built inline editing on Day 1. Every session since has involved going back to fix small things in previous posts — typos, date errors, wording tweaks. Without quick inline editing, each fix was a multi-step process through the voice pipeline. The moment I had a textarea and a Save button, my publishing velocity doubled.
**Transparency scales trust.** The public changelog is a small feature, but it signals something: this content is alive, corrections are acknowledged, and readers can see what changed. For a blog about building in public, that's table stakes.
**Each session fixes friction from the last one.** Day 1 built the foundation. Day 2 made it look right. Day 3 made it usable. The pattern is consistent: build something, use it for real, discover what's broken or slow, fix it next session. The site isn't being designed upfront — it's being discovered through use.
## By the Numbers
- **1 silent auth bug** fixed (soft nav → hard nav)
- **5 files** changed to make the edit pipeline work
- **3 admin actions** per post (type edits, record edits, delete)
- **1 new component** (InlineEditor)
- **1 new frontmatter field** (changelog)
- **2 blog posts** retroactively given changelog entries
- **1 post** merged into another, 1 deleted
- **0 design changes** — all plumbing, all invisible to readers
===
## Day 2: Reskinning with Google Stitch from a Hotel Room
- URL: https://vibescoder.dev/posts/day-two-reskinning-with-google-stitch
- Date: 2026-04-15
- Tags: #next-js
- Reading time: 11 min read
How I used Google Stitch to generate a design system, fed it to Claude, and reskinned my entire blog — including a derived light mode — in a single evening session.
---
## The Starting Point
Day 1 left me with a working blog — dark mode, cyber lime accent, monospace typography. It looked like a VS Code theme had a baby with Medium. Functional, but generic. The kind of thing you get when you describe a vibe in words and let an AI fill in the blanks.
I wanted something with more intentionality. A real design system, not just a color palette. Typography pairings. Surface hierarchy. Component-level specs. The problem: I'm not a designer, I'm building this from my phone, and I don't have Figma open.
Enter Google Stitch.
## Prompting Stitch and the Brand Guidelines Trick
My first pass was generic — I asked Stitch to design a site based on a typical CEO thought leadership blog, Medium-style layouts and functionality. The result featured some rather aggressive neon styling that wasn't what I had in mind.
But Stitch can do something more interesting than interpret vague prompts. Instead of manually tweaking colors and fonts, I pointed it at [Coder’s brand guidelines](https://coder.com/brand) and let the AI extract what it needed — color palettes, typographyt choices, overall visual styling. It essentially created an offshoot of my company's brand identity without me specifying a single hex value or font name. The AI understood the brand context and applied it consistently across the entire site design.
That's the real unlock: if you have existing brand assets anywhere on the web, feed them to Stitch instead of describing a vibe in words.
## What Google Stitch Actually Gives You
[Google Stitch](https://stitch.withgoogle.com/) is a design-to-code tool. You describe what you want (or point it at brand guidelines), and it generates full-page HTML mockups with embedded Tailwind CSS — complete with a color system, typography scale, and component patterns. It also outputs a `DESIGN.md` file that documents the creative direction, naming it with a "Creative North Star" label.
From the brand-informed prompt, it generated a zip file containing:
- **4 page types** — home feed, article view, manifesto/about page, connect/contact page
- **3 variants per page** — each with slightly different layouts and interaction patterns
- **2 complete design systems** — this was the surprise
The zip contained 12 HTML files and 2 `DESIGN.md` documents, each describing a fully distinct visual identity. Not variations on a theme — two completely different design systems with different color palettes, different font stacks, and different component philosophies.
## Two Themes One Zip File
I didn't expect this. When I extracted the zip and started reading the HTML, the first two variants of each page shared one color system, and the third variant used something entirely different.
**Theme A — "The Digital Architect"** lived in the `cyber_ceo/` directory. Editorial, magazine-like. Neon green primary (`#9cff93`), purple secondary, cyan tertiary. Inter for headlines, Newsreader (a serif) for body text, Space Grotesk for labels. Glass cards with green glow effects. The whole thing felt like a Bloomberg Terminal redesigned by a fashion magazine.
**Theme B — "The Neon Brutalist"** lived in `vibes_protocol/`. Completely different personality. Lavender primary (`#dcb8ff`), hot pink secondary (`#f7acff`), coral tertiary (`#ffb4a5`). Space Grotesk for headlines, Inter for body — the font roles reversed from Theme A. Gradient text, gradient buttons, no glass effects. More austere, more technical.
Both themes shared some DNA — Material Design 3 surface token naming, a strict "No-Line Rule" (no 1px borders for layout, only tonal shifts), Space Grotesk for labels in both cases, identical border-radius configs. But they diverged on everything that matters for visual identity.
I had to pick one. I went with B.
## Why the Neon Brutalist
Theme A's green primary was too close to the existing cyber lime accent I was trying to replace. It would have been a lateral move — a nicer version of the same idea. Theme B was a genuine departure. The lavender-pink-coral palette felt warmer and more distinctive. The all-sans-serif font stack (no Newsreader serif) was cleaner for a technical blog. And the gradient text on the hero felt like it had more personality than a single accent color.
The `DESIGN.md` for Theme B was opinionated in useful ways. "1px solid borders are strictly prohibited for sectioning." "Shadows are never pure black." "Never use pure white text — use `on-surface` (`#e2e2e2`)." "If accessibility requirements demand a border, use the Ghost Border: `outline-variant` at 15% opacity." These aren't vague mood boards — they're implementable constraints.
## The Reskin
Applying the design system was systematic work. The blog has a clear architecture — `globals.css` for tokens, `layout.tsx` for the shell, then 7 components and 5 page files that compose the public UI. Admin pages and API routes stay untouched.
The mapping was straightforward:
| Old | New |
|-----|-----|
| Background `#0A0A0A` | `#121414` (warmer) |
| Accent `#A3E635` (lime) | `#dcb8ff` (lavender) |
| Body font: Inter only | Headlines: Space Grotesk, Body: Inter, Mono: Fira Code |
| Card borders: `1px solid #1F1F1F` | Tonal surface shifts, ghost borders at 10% |
| Hover glow: lime | Hover glow: purple neon |
| Footer hover: lime | Footer hover: coral `#FF8067` |
The font change was the most impactful. Adding Space Grotesk for headlines and labels gave the site a geometric, technical feel that Inter alone couldn't deliver. Fira Code replaced JetBrains Mono for code blocks — a subtle change, but the ligatures are nicer.
Every component got the same treatment: replace hardcoded hex values, swap font references, adjust hover/focus states to use the new accent colors. The reading progress bar went from a lime gradient to a lavender-to-pink gradient. Selection highlighting went purple. The hero title got gradient text (`from-primary to-secondary`).
One build. Zero errors. Pushed to main, Vercel deployed. The whole reskin took about 20 minutes of active direction.
## The Light Mode Question
Then I asked: "The Stitch design should have both light and dark theme designs. Can you find the light theme and make it togglable?"
It didn't. Neither `DESIGN.md` file mentions light mode. Both are explicitly dark-only systems. The vibes_protocol doc literally says "embrace the starkness of a dark environment." Every HTML variant uses `<html class="dark">`. There is no light palette anywhere in the Stitch output.
This is worth noting as a Stitch limitation — or maybe a reflection of the prompt I gave it. Either way, if you want light mode from Stitch, you'll need to ask for it explicitly or derive it yourself.
## Deriving a Light Theme
We derived one. The approach: invert the surface hierarchy and deepen the accents for contrast on white backgrounds.
The dark palette uses pastel accents on dark surfaces — lavender `#dcb8ff` pops against `#121414`. But that same lavender fails WCAG AA contrast on white. So every accent needed to be darkened for light mode:
| Token | Dark | Light | Reasoning |
|-------|------|-------|-----------|
| Primary | `#dcb8ff` | `#7c3aed` | Violet-600, AA on white |
| Secondary | `#f7acff` | `#a21caf` | Fuchsia-700, AA on white |
| Tertiary | `#ffb4a5` | `#ea580c` | Orange-600, AA on white |
| Background | `#121414` | `#faf8fc` | Warm purple-tinted white |
| Cards | `#1a1c1c` | `#ffffff` | Pure white |
| Text | `#e2e2e2` | `#1a1625` | Near-black, purple-tinted |
The surfaces got a subtle purple tint — `#faf8fc` instead of pure `#fafafa` — so the light theme still feels related to the dark one. Same family, different time of day.
## The Token Refactor
Here's what made the light mode actually work: we had to rip out every hardcoded hex color and replace it with semantic Tailwind tokens.
The first commit (the reskin) used hardcoded values everywhere — `text-[#e2e2e2]`, `bg-[#1a1c1c]`, `hover:text-[#dcb8ff]`. That's fine for a single theme. For two themes, it's a dead end. You can't conditionally override arbitrary hex values in CSS.
The second commit converted everything to token classes: `text-on-surface`, `bg-surface-low`, `hover:text-primary`. These compile to `var(--color-on-surface)`, `var(--color-surface-low)`, etc. — CSS custom properties that Tailwind v4 generates from the `@theme` block. Then a `[data-theme="light"]` selector overrides all the variables in one place.
Every component went through this:
```
text-[#e2e2e2] → text-on-surface
text-[#cec2d4] → text-on-surface-variant
text-[#dcb8ff] → text-primary
bg-[#1a1c1c] → bg-surface-low
bg-[#282a2a] → bg-surface-high
border-[#4c4452] → border-outline-variant
```
Twelve files changed, zero admin files touched. The token refactor was the real work — the light palette definition was just a block of CSS variable overrides.
## Preventing Flash
One thing that's easy to get wrong with theme toggles: the flash of wrong theme on page load. If you default to dark in HTML and the user has light saved in localStorage, they see a dark frame before React hydrates and flips the theme. It's jarring.
The fix is an inline `<script>` in `<head>` that runs before the browser paints:
```javascript
(function(){
var t = localStorage.getItem("theme");
if (!t) t = window.matchMedia(
"(prefers-color-scheme:light)"
).matches ? "light" : "dark";
document.documentElement.setAttribute("data-theme", t);
})()
```
No React, no hydration — just a synchronous DOM attribute set before the first frame. The theme toggle component then picks up the same state on mount.
## The Mobile Workflow
The entire process — from design to deployed site — happened from my phone in a hotel room. The pipeline looks like this:
1. **Design in Google Stitch** — create and refine the site design in the browser
2. **Export to mobile** — download the zip file to iPhone Files
3. **Upload to GitHub** — use GitHub's web interface to push the zip to the repo
4. **Agent processing** — Coder agents detect the new file, extract it, and apply the design
In practice: Stitch exports a zip, which downloads straight to the iPhone Files app. From there I opened GitHub's web UI in Safari, navigated to the repo, and uploaded the zip to a branch. Once it landed in the repo, Coder Agents had access to the file — they extracted the zip, read the HTML and `DESIGN.md` files inside, and applied the design system to the codebase.
It works, but the iOS Files → GitHub upload step is friction. You're bouncing between apps, navigating folder structures on a phone keyboard. The ideal would be direct integration between design tools and deployment platforms, cutting out the file management in between. These are the kinds of workflow seams worth smoothing out.
## What I Learned
**Stitch gives you more than you expect.** I asked for a redesign and got two complete design systems with documented creative direction. The `DESIGN.md` files alone are worth the exercise — they articulate design decisions in a way that's directly implementable. "No-Line Rule," "Ghost Border Fallback," "7-tier surface hierarchy." These are the kinds of constraints that make a design system cohesive.
**Stitch doesn't give you everything.** No light mode. No responsive breakpoint specs. No animation timing guidance. No accessibility annotations beyond a brief mention of WCAG AA. The HTML it generates is static Tailwind — good for extracting a design system, not for dropping into a production app.
**Two themes in one export is both a feature and a friction point.** It's great to have options. But if you're feeding this to an AI coding agent, you need to identify which variant maps to which system and make a choice. The variants aren't labeled in the filename — you have to read the CSS to figure out which design system each one belongs to.
**Token-first is the only way to do themes.** If I'd started with semantic tokens on Day 1, the light mode would have been a 20-line CSS change instead of a 12-file refactor. Lesson learned: even if you're building dark-only, use design tokens. Future you will thank present you.
**The design-to-code pipeline is real.** Stitch → Claude → deployed site, in one session. No Figma. No design handoff. No "pixel-perfect" arguments. A generated design system, interpreted by an AI coding agent, applied to a production codebase. The fidelity isn't perfect — it's an interpretation, not a screenshot recreation. But it's good enough to ship, and you can refine from there.
## By the Numbers
- **2 design systems** extracted from one Stitch export
- **12 HTML mockups** analyzed (4 page types × 3 variants)
- **13 files** changed across 2 commits
- **1 new component** (ThemeToggle)
- **~50 color tokens** mapped from hardcoded hex to semantic names
- **0 admin files** touched
- **2 builds**, both zero errors
- **1 evening session**, still from my phone
===
## Hello World: Coding with Claude in a Cabana
- URL: https://vibescoder.dev/posts/day-one-building-vibescoder-dev
- Date: 2026-04-11
- Tags: #next-js
- Reading time: 4 min read
How I built a full-featured personal blog with an AI-powered content pipeline in a single session — from a cabana in Cabo, on my iPhone.
---
## From a Cabana in Cabo
I'm writing this from a lounge chair in Cabo San Lucas. No laptop. Just my iPhone, a [Coder](https://coder.com) workspace, and Claude as my development partner.
About 90 minutes ago I opened a chat and said "we're going to create a personal website." Ninety minutes later — between sips of something cold — I had a fully functional blog with a custom design, an AI-powered content pipeline, and admin tools for managing everything. Every line of code was written by Claude, directed by me, from a phone screen in a cabana.
This is what building software looks like in 2026. Here's what happened.
## What Got Built
### The Blog
Started from zero. Scaffolded a Next.js 16 project with the App Router, deployed to Vercel, and wired up:
- **MDX content layer** — Blog posts are `.mdx` files with YAML frontmatter. No database, no CMS — just files in git. Simple, portable, and version-controlled.
- **Tailwind CSS v4** — The initial design was clean but generic. We restyled everything based on a "Medium meets VS Code" aesthetic: dark-first palette, cyber lime accent, monospace metadata, and subtle glow effects on hover.
- **Syntax highlighting** — rehype-pretty-code with Shiki for beautiful code blocks. This is a dev blog, after all.
- **Animations** — Framer Motion entrance effects. Elements fade in and slide up on page load, staggered across the feed.
- **Reading progress** — A thin accent-colored bar at the top of article pages, styled like a terminal loading indicator.
- **Tag system** — Every post can have tags with index and filter pages.
- **Dark mode by default** — The soul of the site.
The branding went through a quick evolution: "The Vibe Coder" → "Vibes Coder" once we landed on the `vibescoder.dev` domain. Every reference updated in one pass.
### The Content Pipeline
This is the part I'm most excited about. Behind the scenes, the site has a full content management system with a voice-to-blog workflow:
- **Voice recording** — I can dictate my thoughts directly in the browser. The Web Speech API handles real-time transcription — words appear as I speak. Continuous, uninterrupted recording for 10+ minutes.
- **Artifact uploads** — Drag-and-drop images, PDFs, text files, and code files as context. Claude ingests everything alongside the transcript.
- **AI generation** — Claude Sonnet transforms the raw transcript and artifacts into a polished MDX blog post with frontmatter, headings, code blocks — the whole thing. The style prompt is configurable.
- **One-click publishing** — Hit publish and the post is committed to GitHub, which triggers a Vercel deploy. Live in seconds.
- **Inline editing** — I can edit or delete any post directly from the site. Changes commit to the repo and auto-deploy.
The entire authoring flow is: talk → review → generate → publish. No context switching, no manual git commands, no deploy scripts.
### Security Pass
Before shipping, we ran a full security review. Fixed timing-safe password comparison, closed a path traversal vector in file uploads, added security headers, locked down the API surface, and scrubbed any sensitive details from public content. The kind of thing you do before you let the internet see your work.
## The Tech Stack
| Layer | Choice | Why |
|-------|--------|-----|
| Framework | Next.js 16 (App Router) | Vercel-native, React Server Components |
| Styling | Tailwind CSS v4 | Utility-first, fast iteration |
| Content | MDX + gray-matter | Git-based, no vendor lock-in |
| Syntax | rehype-pretty-code + Shiki | Beautiful code blocks |
| Animation | Framer Motion | Smooth entrance effects |
| AI | Claude Sonnet (Anthropic SDK) | Blog generation from transcripts |
| Transcription | Web Speech API | Free, real-time, browser-native |
| Hosting | Vercel | Auto-deploy on push to main |
| Dev Environment | Coder | Cloud workspace, accessible from anywhere |
## By the Numbers
- **~90 minutes** from first prompt to published summary
- **43 source files** created
- **~2,500 lines** of code
- **0 lines** written by hand — every line authored by Claude, directed by me
- **1 iPhone** — no laptop touched
## What's Next
This is Day One. The foundation is solid — a git-based blog with an AI-powered authoring pipeline. Future sessions will add:
- Custom style prompt tuning
- Analytics dashboard
- RSS feed
- OG image generation
- Video content support
- Search
The whole thing was built in a Coder workspace with Claude as the coding agent — from a phone, poolside, in Mexico. If that's not the future of software development, I don't know what is.
Welcome to Vibes Coder.
===